
Search
Get started
Use our models
Building with Llama
How to guides
Integration guides
Llama DocumentationBuilding with LlamaHow to guidesVision Capabilities


Products
Documentation
Resources
Terms & policies
Llama models can now take Image + Text inputs, enabling you to interact with the model in new ways. Multimodal inputs result in conversations that are more natural and flexible.
The new multimodal models, in 11B and 90B, support image reasoning use cases. Examples are document-level understanding–including charts and graphs, captioning of images, and visual grounding tasks–such as directionally pinpointing objects in images based on natural language descriptions.
These models also make it natural to interact with the world by bridging the gap between vision and language: extracting details from an image, understanding the scene, and then crafting a sentence or two that can be used as a caption to tell the story depicted in the image.
The Llama 3.2 multimodal models work well on:
Llama 3.2 shares the same text-based models as Llama 3.1 8B and 70B, so you can expect the same behavior when performing text-only tasks. This means that, for text-only inference, the models can do tool-calling out of the box, allowing them to essentially work as drop-in replacements for the pretrained Llama 3.1 text models.
The following block of code demonstrates using the Llama 3.2 11B model with the Hugging Facetransformers library. For an end-to-end example, see this quick-start in llama-cookbook inference.
import torch
from PIL import Image as PIL_Image
from transformers import MllamaForConditionalGeneration, AutoProcessor, MllamaProcessor

model_id = "meta-llama/Llama-3.2-11B-Vision-Instruct"

model = MllamaForConditionalGeneration.from_pretrained(model_id, device_map="auto", torch_dtype=torch.bfloat16)
processor = MllamaProcessor.from_pretrained(model_id)

with open("Path_to_Image", "rb") as f:
    raw_image = PIL_Image.open(f).convert("RGB")
conversation = [
    {
    "role": "user",
    "content": [
        {"type": "image"},
        {"type": "text", "text": "Describe this image in two sentences"},
        ],
    },
]

prompt = processor.apply_chat_template(conversation, add_generation_prompt=True,tokenize=False)

inputs = processor(prompt, raw_image, return_tensors="pt").to(model.device)
output = model.generate(**inputs, temperature=0.7, top_p=0.9, max_new_tokens=512)

print("text&image_output: ",processor.decode(output[0])[len(prompt):])The following examples were run on Llama 3.2 11B to showcase the ways that you can prompt the new vision models. For each example, the left side shows the text prompt and image used, and the right side shows the response from the model.
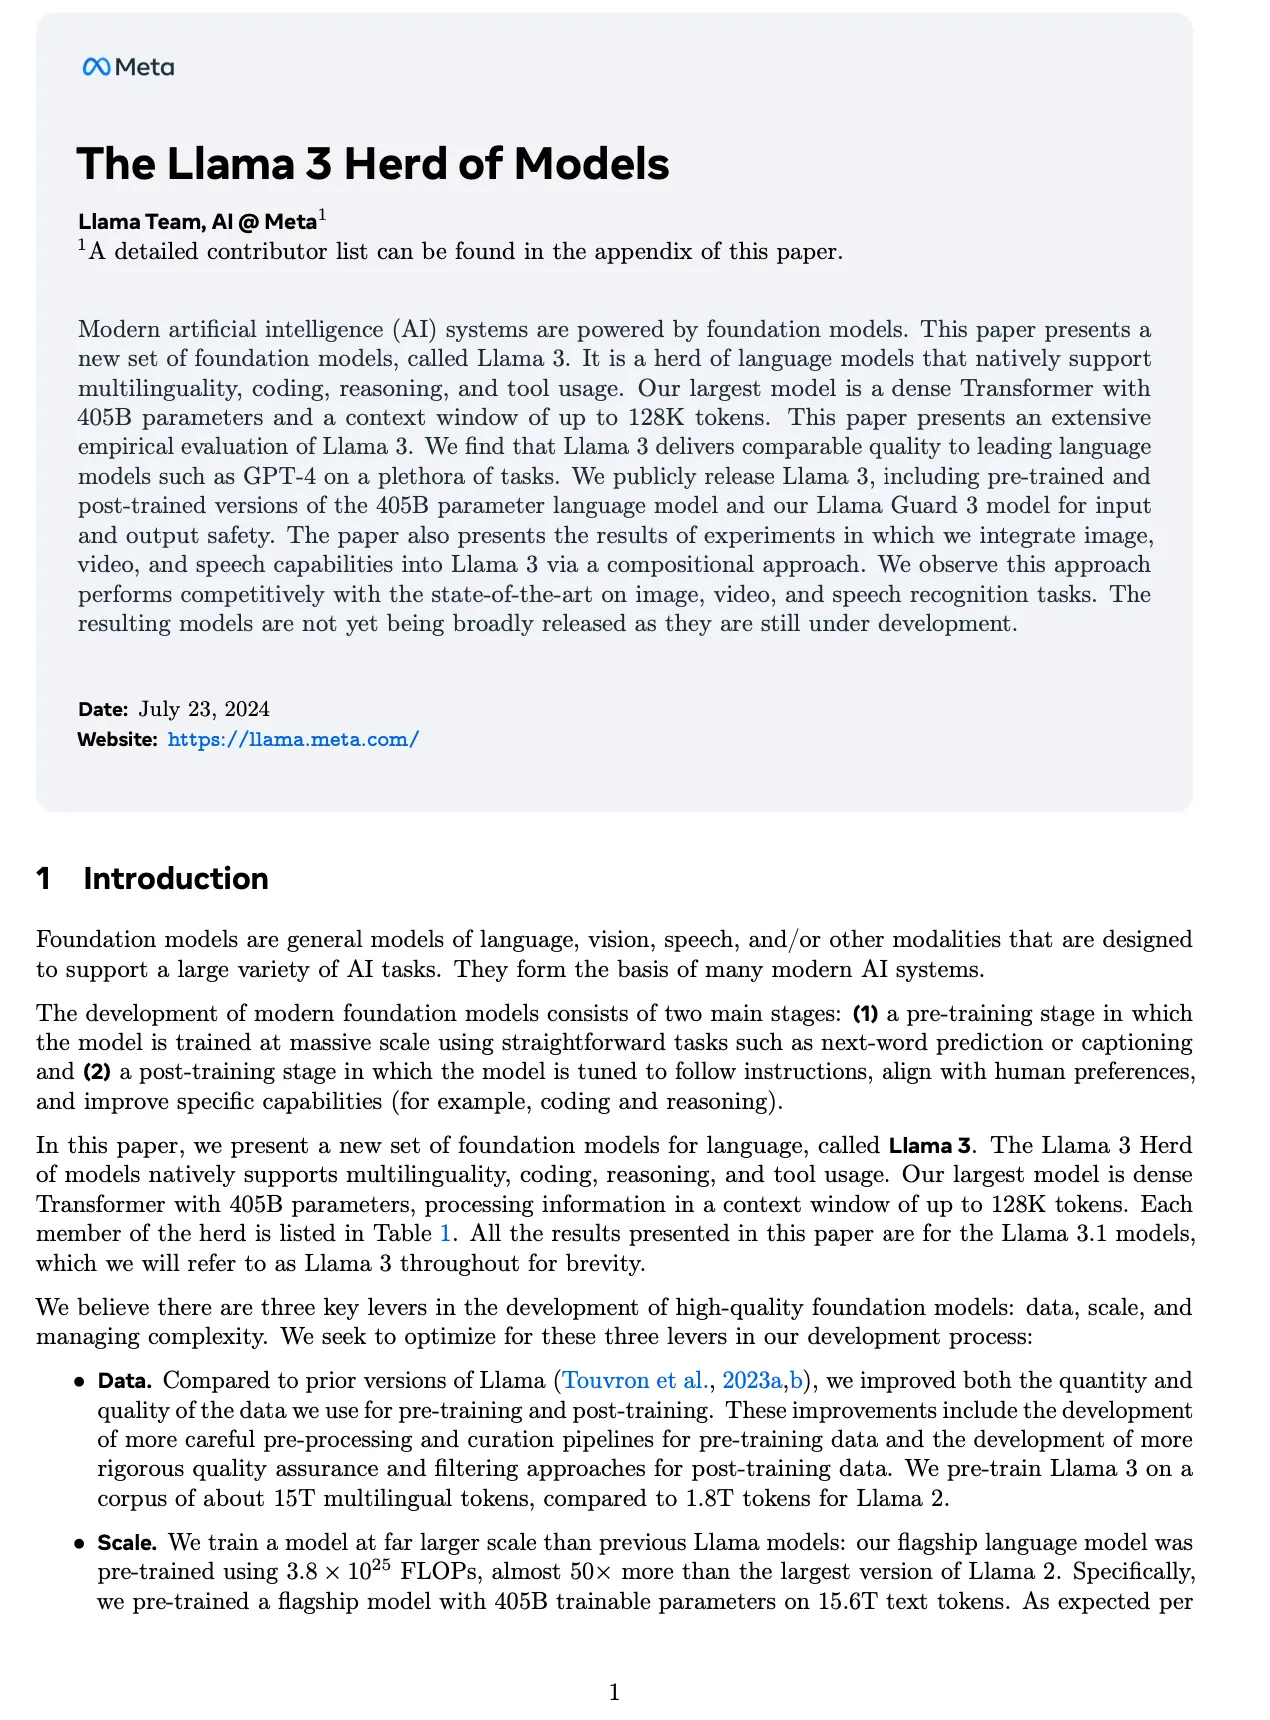
Describe this image in as much detail as possible, can you give me 3 most interesting facts from the paper?
+
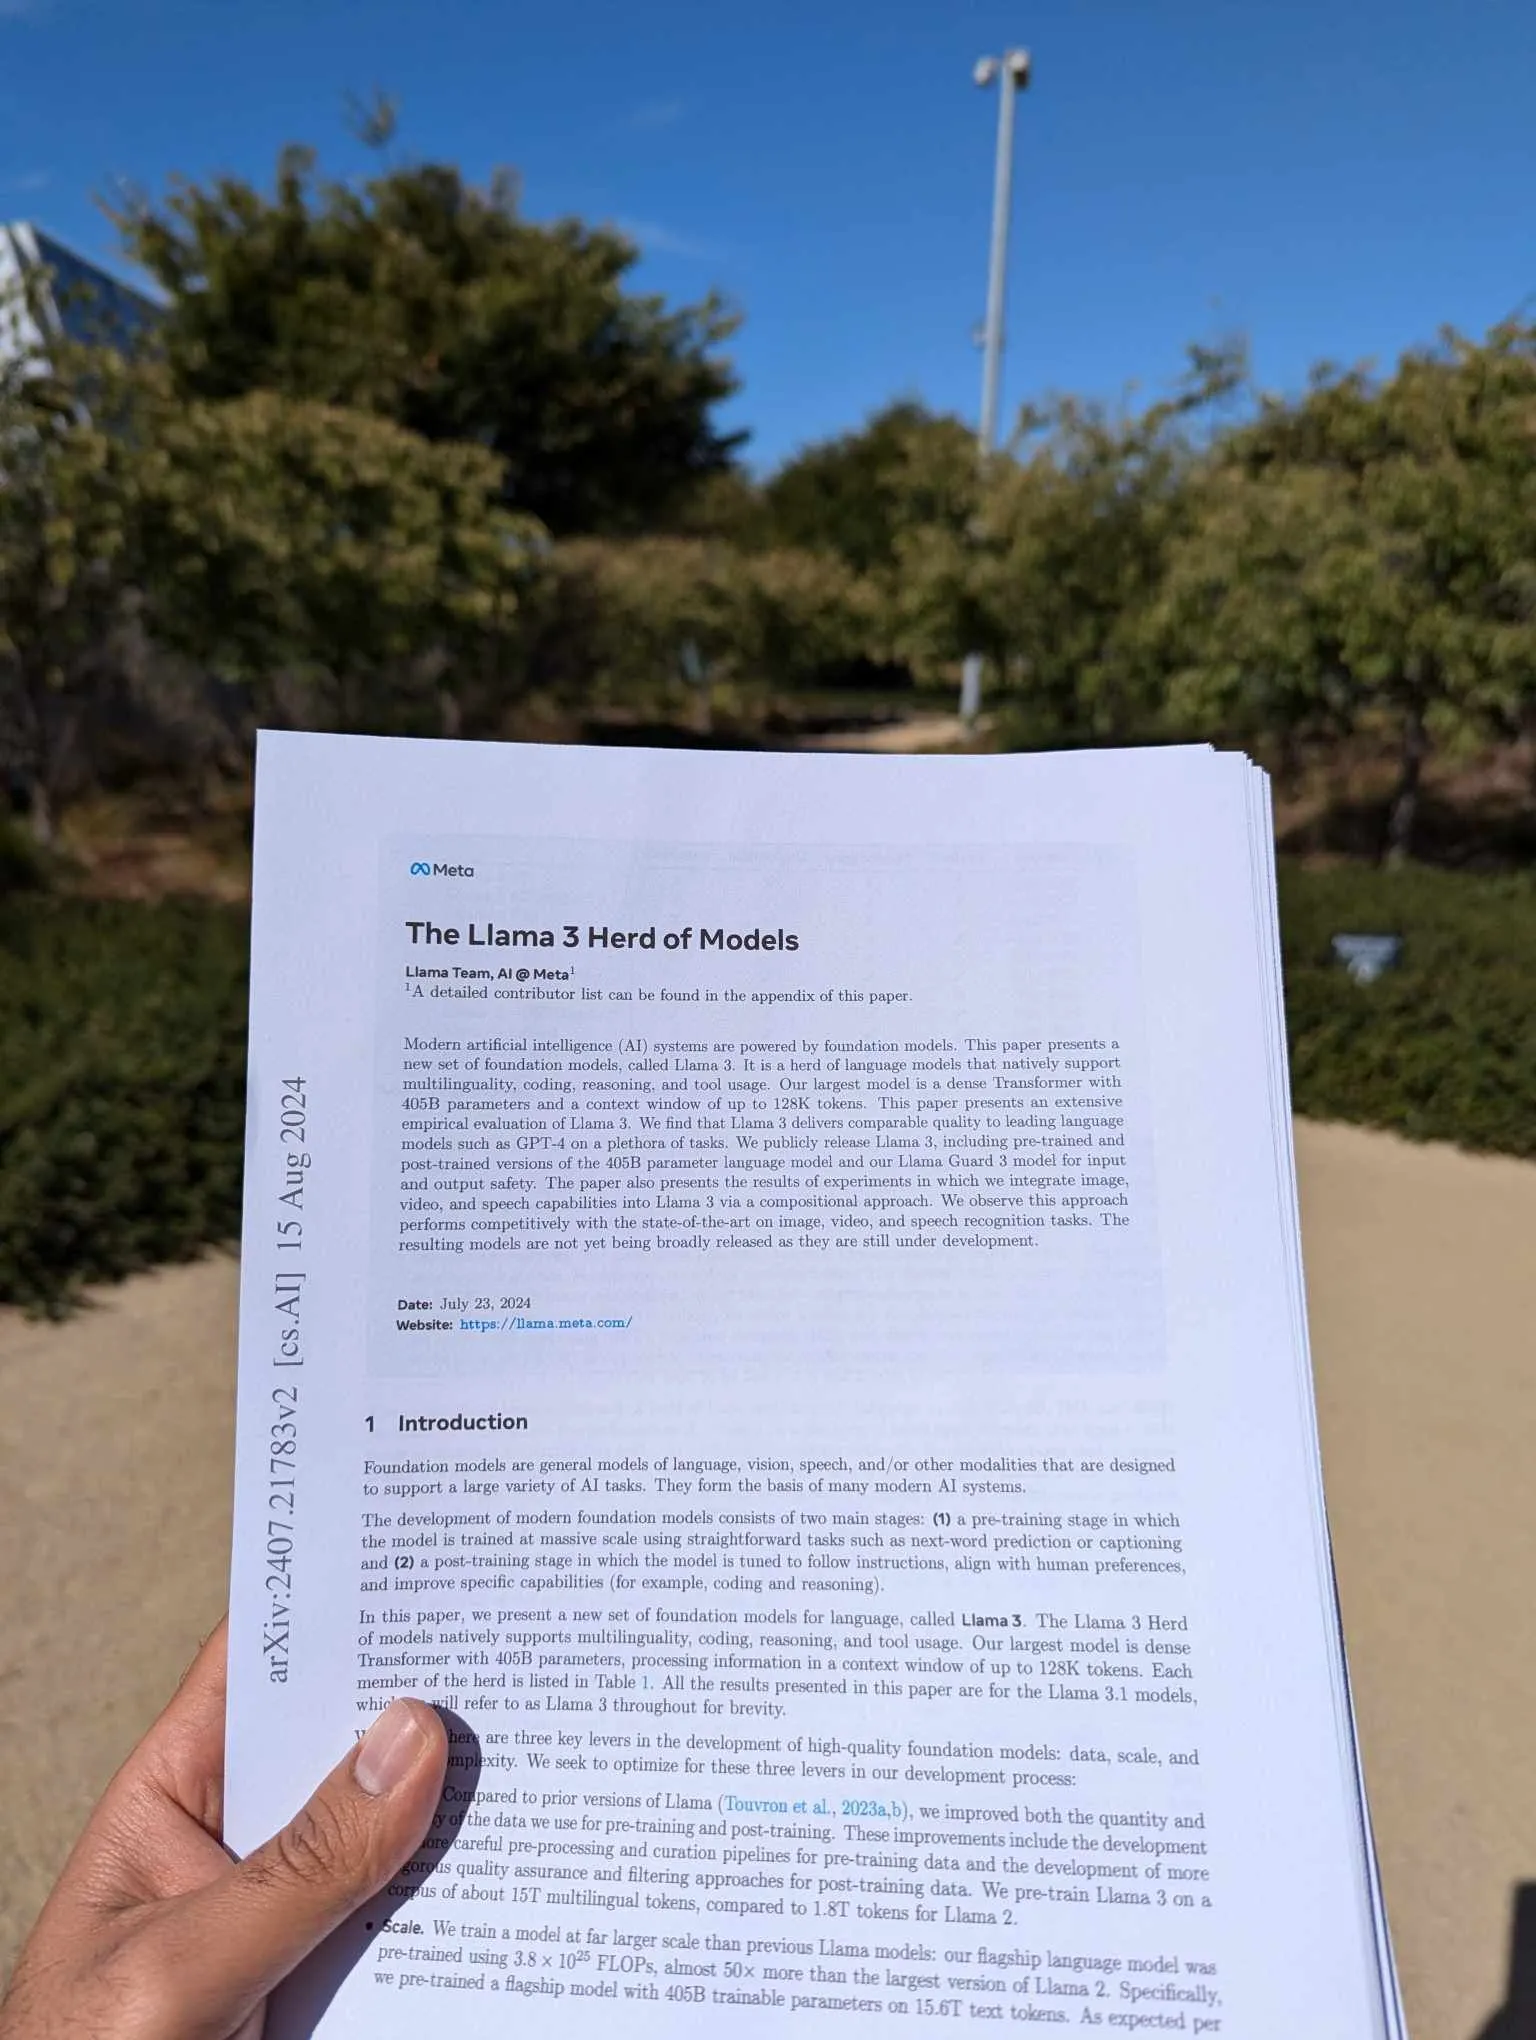
The image shows a hand holding a white paper with a document on it. The document is titled "The Llama 3 Herd of Models" and has a date and website listed. It appears to be an academic paper or report about the Llama 3 model.
Largest Language Model: Llama 3 is a dense Transformer with 405B parameters and a context window of up to 128K tokens. This makes it one of the largest language models in the world.
Training Data: The paper states that Llama 3 was trained on 3.8 x 10^18 FLOPs, which is almost 50 times more than the largest version of Llama 2. This indicates that Llama 3 requires a significant amount of computational resources to train.
Performance: The paper reports that Llama 3 outperforms previous Llama models on a pre-trained version of the 15T multilingual tokens, compared to 1.8T tokens for Llama 2. This suggests that Llama 3 has improved performance on natural language processing tasks.
Please help me come up with a creative listing for this rental room, pay close attention to the image and use the following attributes in your writeup:
{city:fiction_land,
                      proximity_to_bus_stop:0.2 Mile, promixity_to_city_center:2 Miles,
                      rent: 40$/night}
+
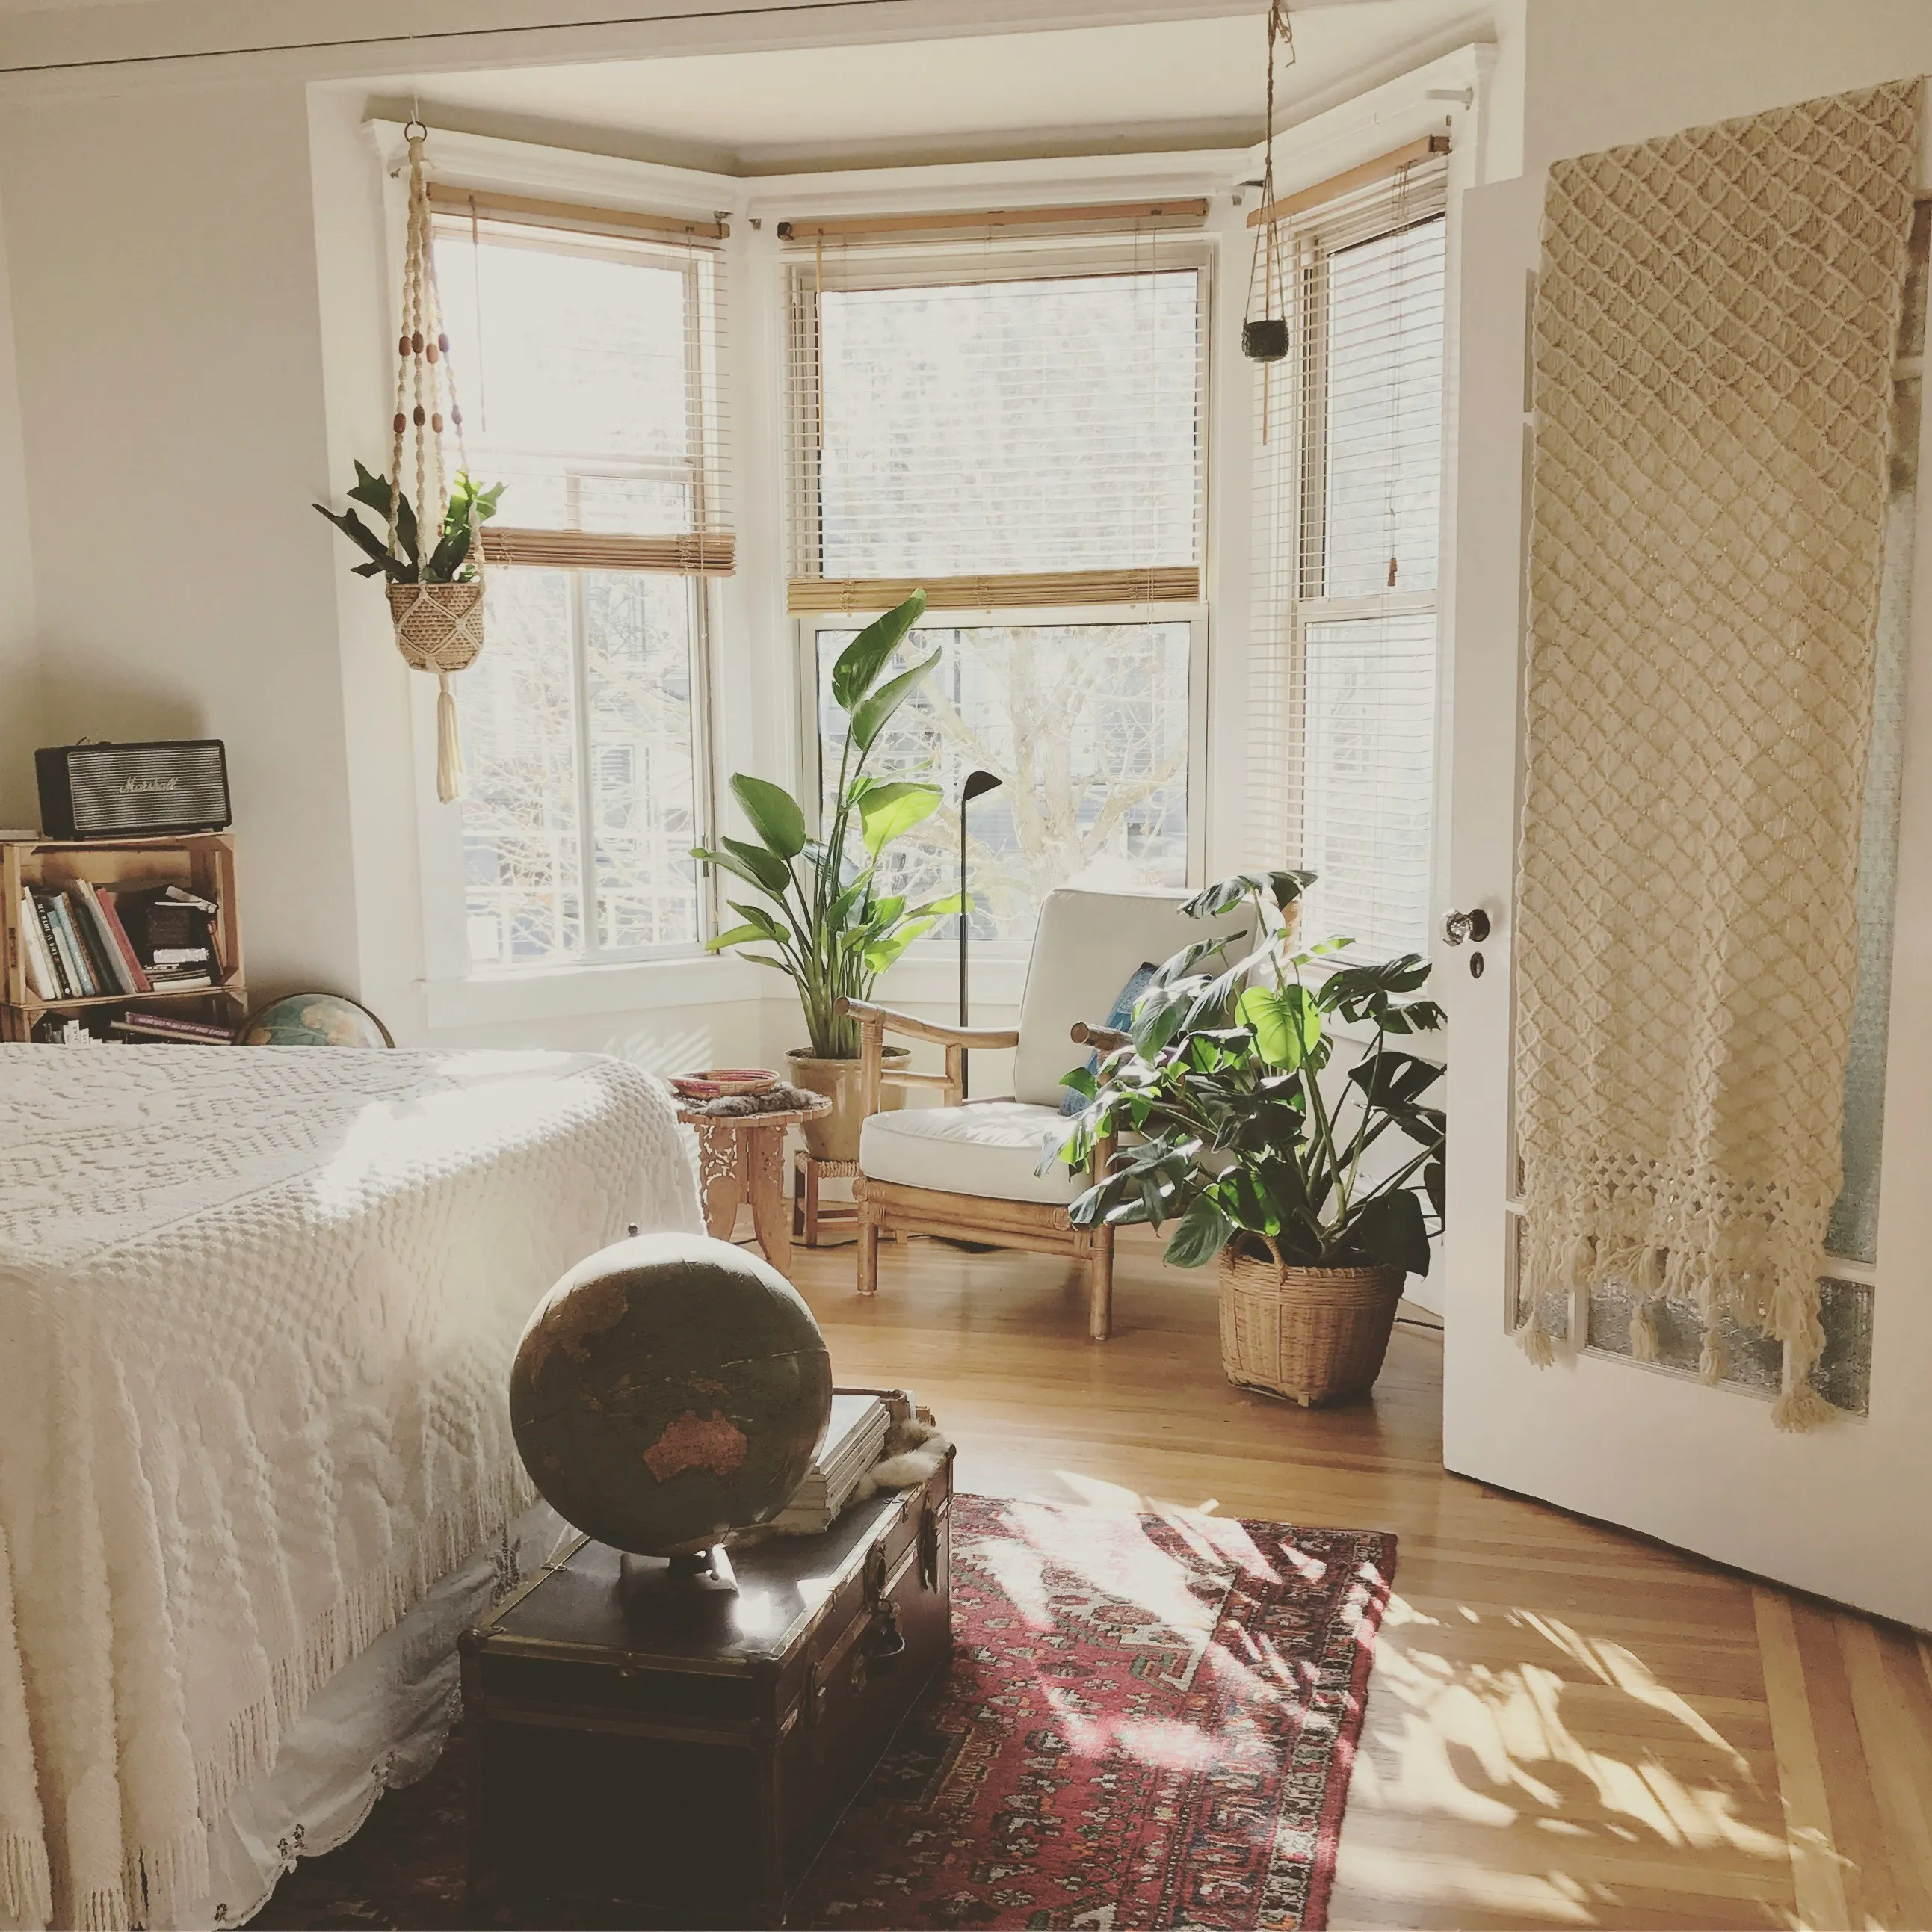
Escape to the heart of Fiction Land and experience the perfect blend of comfort, nature, and convenience in our enchanting rental room. Nestled in a charming neighborhood, our cozy abode offers a serene retreat amidst the bustling city.
Roomy Retreat: Enjoy the warmth of our inviting bedroom, adorned with plush furnishings and plenty of natural light pouring in through the large windows.
Nature's Serenade: Unwind in the peaceful surroundings, surrounded by lush greenery and the soothing sounds of nature.
Comfy Haven: Snuggle up in our plush beds, featuring crisp white linens and a few throw pillows to ensure a restful night's sleep.
Bohemian Charm: The room's eclectic decor adds a touch of whimsy and personality to the space, making you feel right at home.
City Center Convenience: Located just 2 miles from the city center, you'll be close to all the action, yet far enough to enjoy the tranquility of our neighborhood.
Bus Stop Proximity: Our rental is a short 0.2-mile stroll from the bus stop, making it easy to get around Fiction Land without breaking a sweat.
Your Home Away from Home: Our rental room is available for 40$/night, offering an affordable and cozy retreat for your stay in Fiction Land.
Join us in our enchanting rental room, where comfort, nature, and convenience come together in perfect harmony. Book your stay today and discover the magic of Fiction Land!
Keywords: Fiction Land, city center, bus stop, proximity, rent, 40$/night, cozy, natural light, plush furnishings, greenery, nature, eclectic decor, bohemian, whimsy, personality, throw pillows, crisp white linens, plush beds, restful sleep, serene, retreat, charming, neighborhood, urban oasis, convenience, amenities, location, availability.
Look at the image and help me guess the calories by thinking step by step and listing out calories of every item at the end give me estimate of calories
+
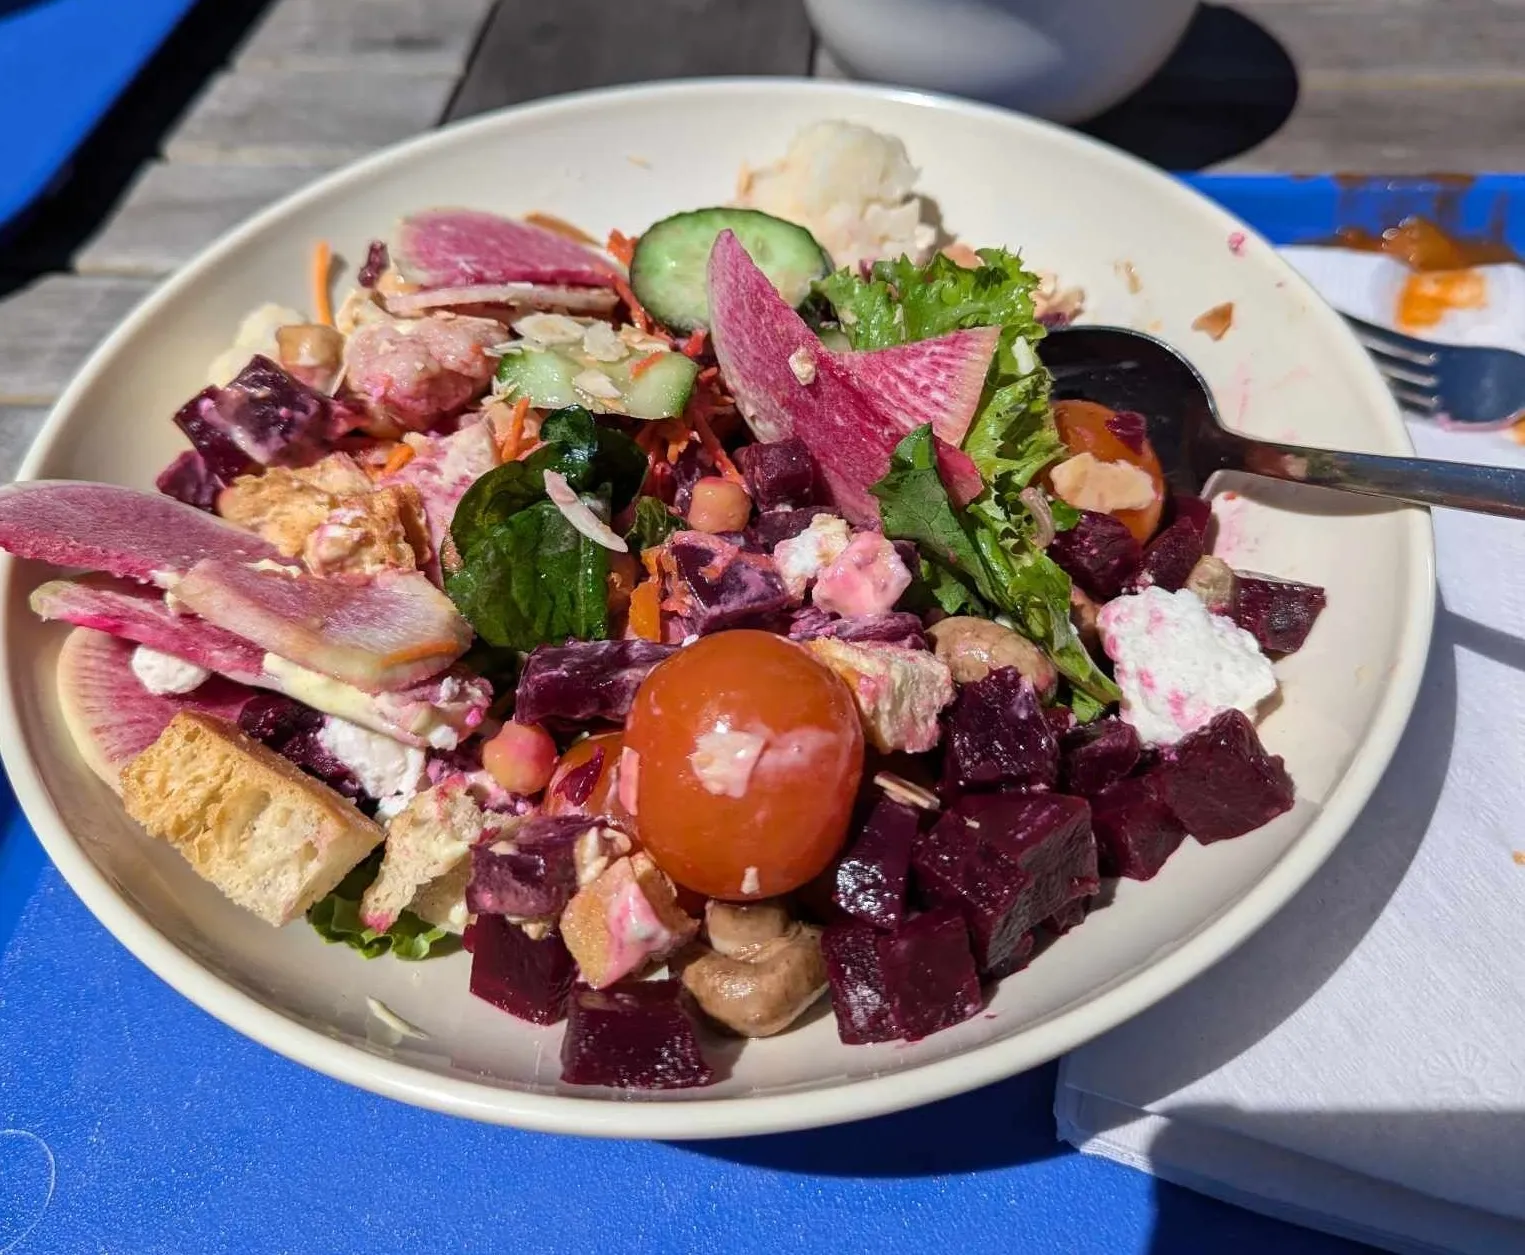
1. Leafy Greens: Typically low in calories, about 20-50 calories per cup.
2. Beets: Approximately 65 calories per cup, cooked.
3. Cherry Tomatoes: About 20 calories per cup.
4. Cucumber: Roughly 16 calories per cup, sliced.
5. Carrots: About 45 calories per cup, shredded.
6. Mushrooms: Approximately 15 calories per cup, sliced.
7. Watermelon Radish: Very low in calories, about 20 calories per cup, sliced.
8. Croutons: Highly variable depending on size and type; assume 50-100 calories for a small amount.
9. Feta Cheese: Roughly 100 calories per ounce, crumbled.
10. Salad Dressing: Can vary widely; assume a light vinaigrette dressing around 100 calories for 2 tablespoons.
Now, adding these estimates together gives us:
Total Estimated Calories: 490 calories
Please note, this is a rough estimate and actual calorie counts may vary based on the specific ingredients, their quantities, and the exact preparation methods. Additionally, if the salad also contains proteins like chicken or fish, those would significantly increase the total calorie count.Is 5 cans of this too much sugar?
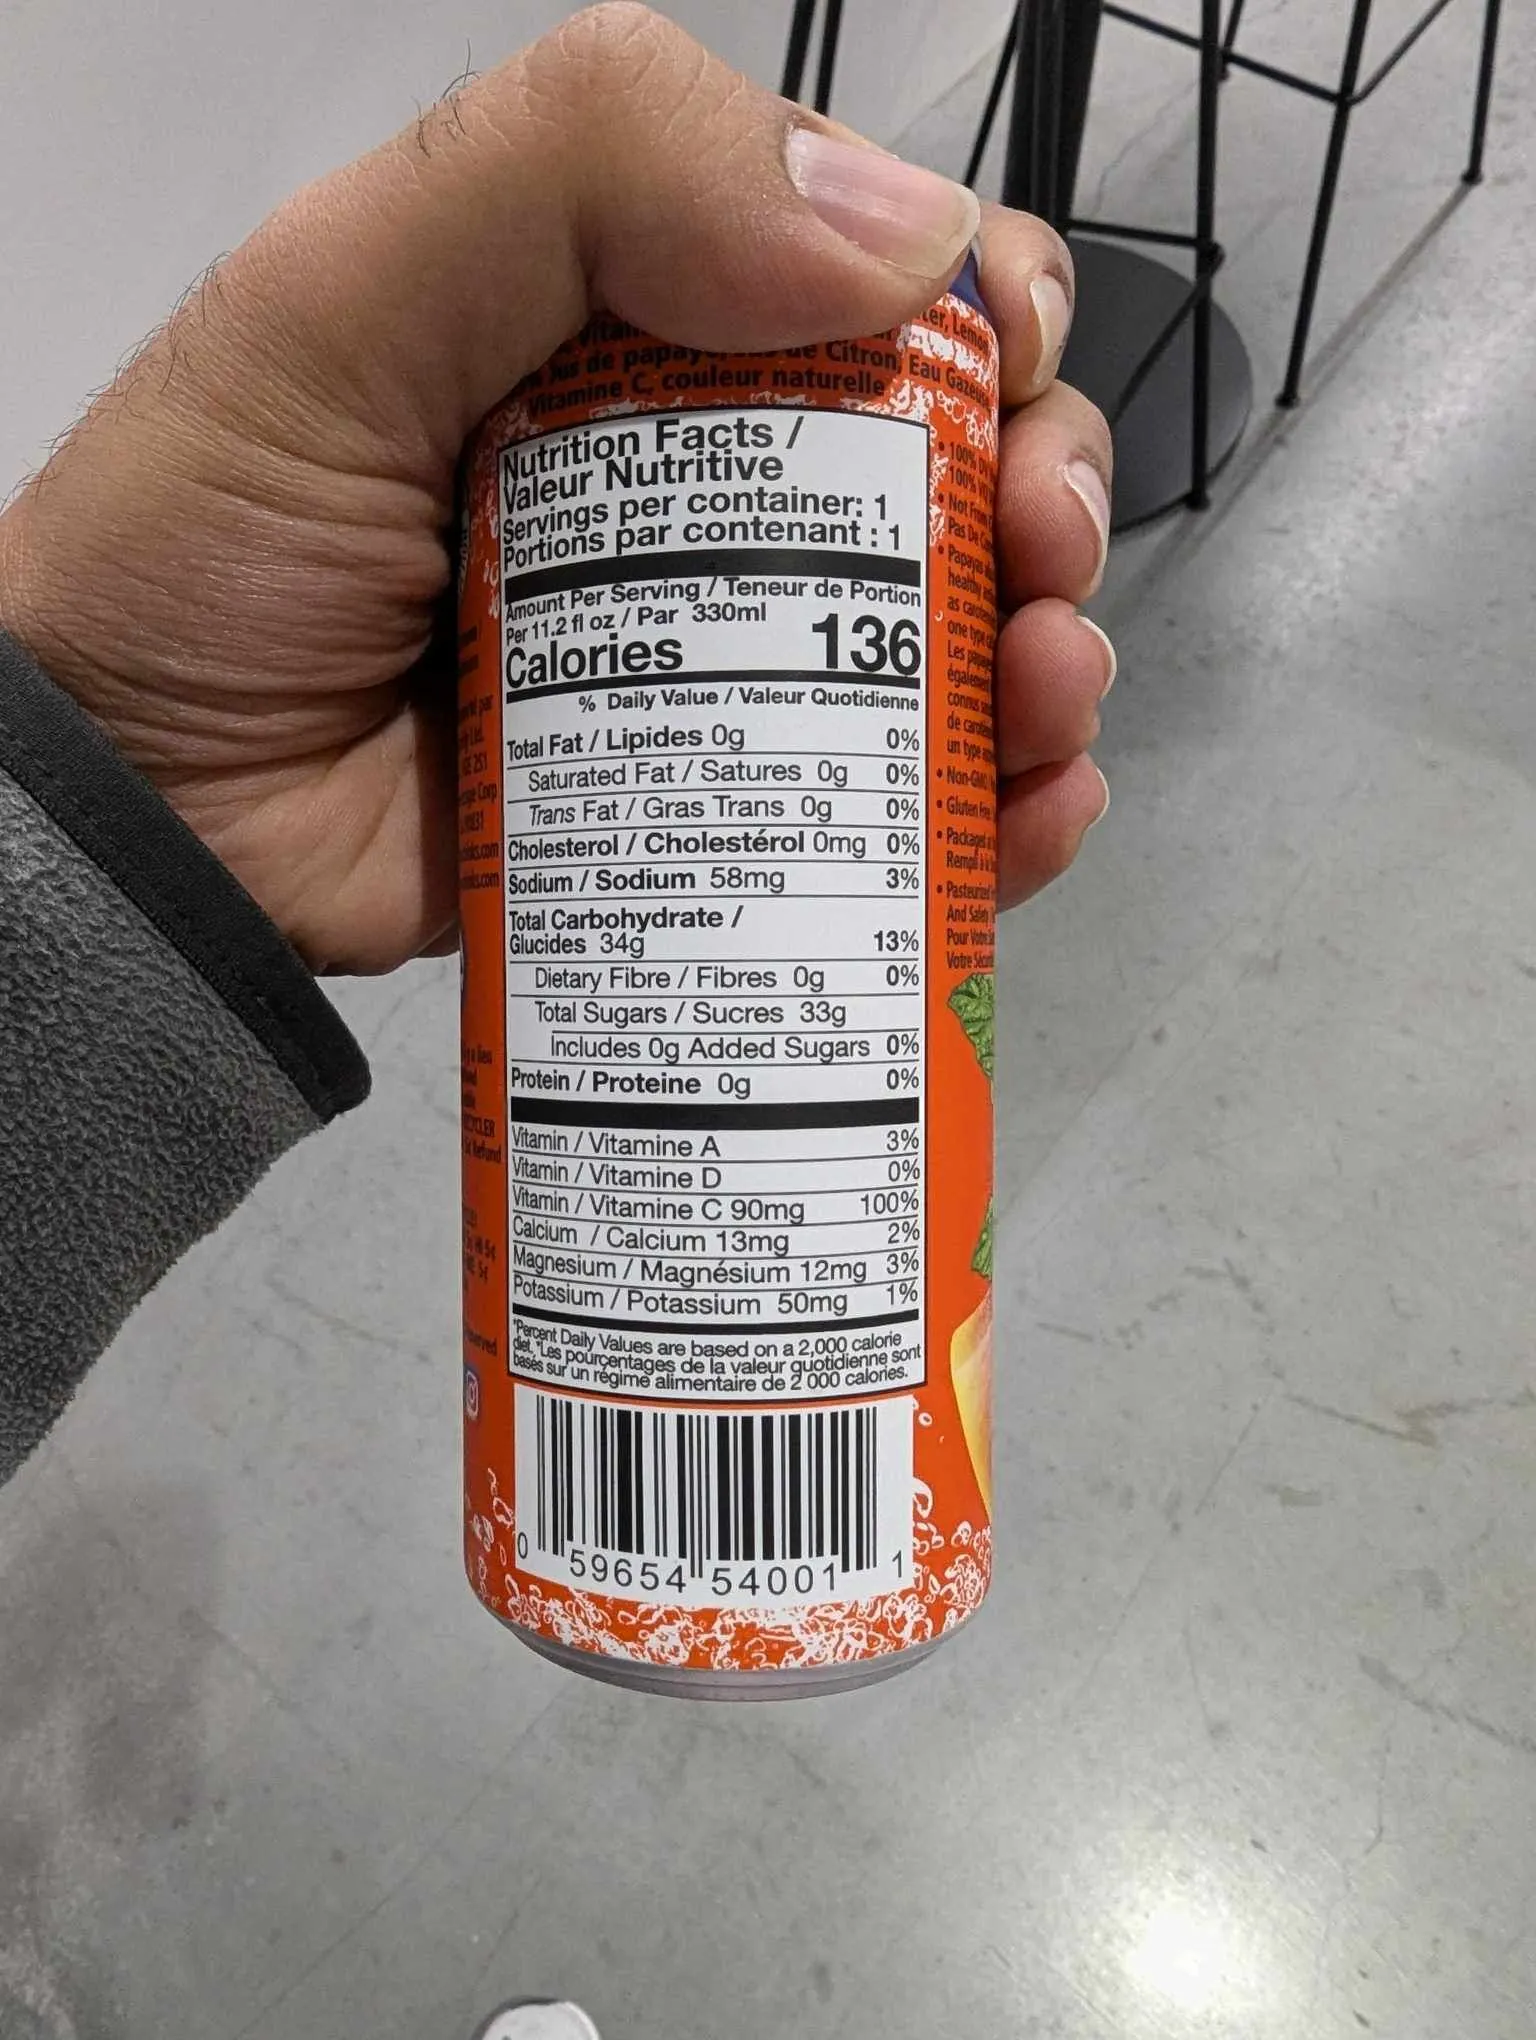
The can in the image has 33 grams of sugar, which is a significant amount. The American Heart Association recommends that women consume no more than 25 grams (6 teaspoons) of added sugar per day, and men consume no more than 36 grams (9 teaspoons) per day.
5 cans of this drink would add up to 165 grams of sugar, which is more than 6 times the recommended daily intake for women and more than 4 times the recommended daily intake for men. Consuming this much sugar can lead to a range of health problems, including obesity, type 2 diabetes, and heart disease.
It's important to note that the nutritional label on the can only includes the amount of added sugars, not the total amount of carbohydrates. Therefore, it's possible that the can contains other sources of carbohydrates that are not listed.
In general, it's best to limit your intake of sugary drinks like this one to special occasions or to consider alternatives that are lower in sugar. It's also important to read the nutrition label carefully and be aware of the ingredients and nutritional content of the products you consume.
You will be helping me configure this machine, look at this image and tell me what instructions do I wash my delicate blanket under, that suggests less movement and cold water wash. Can you tell me the exact settings to configure and where?
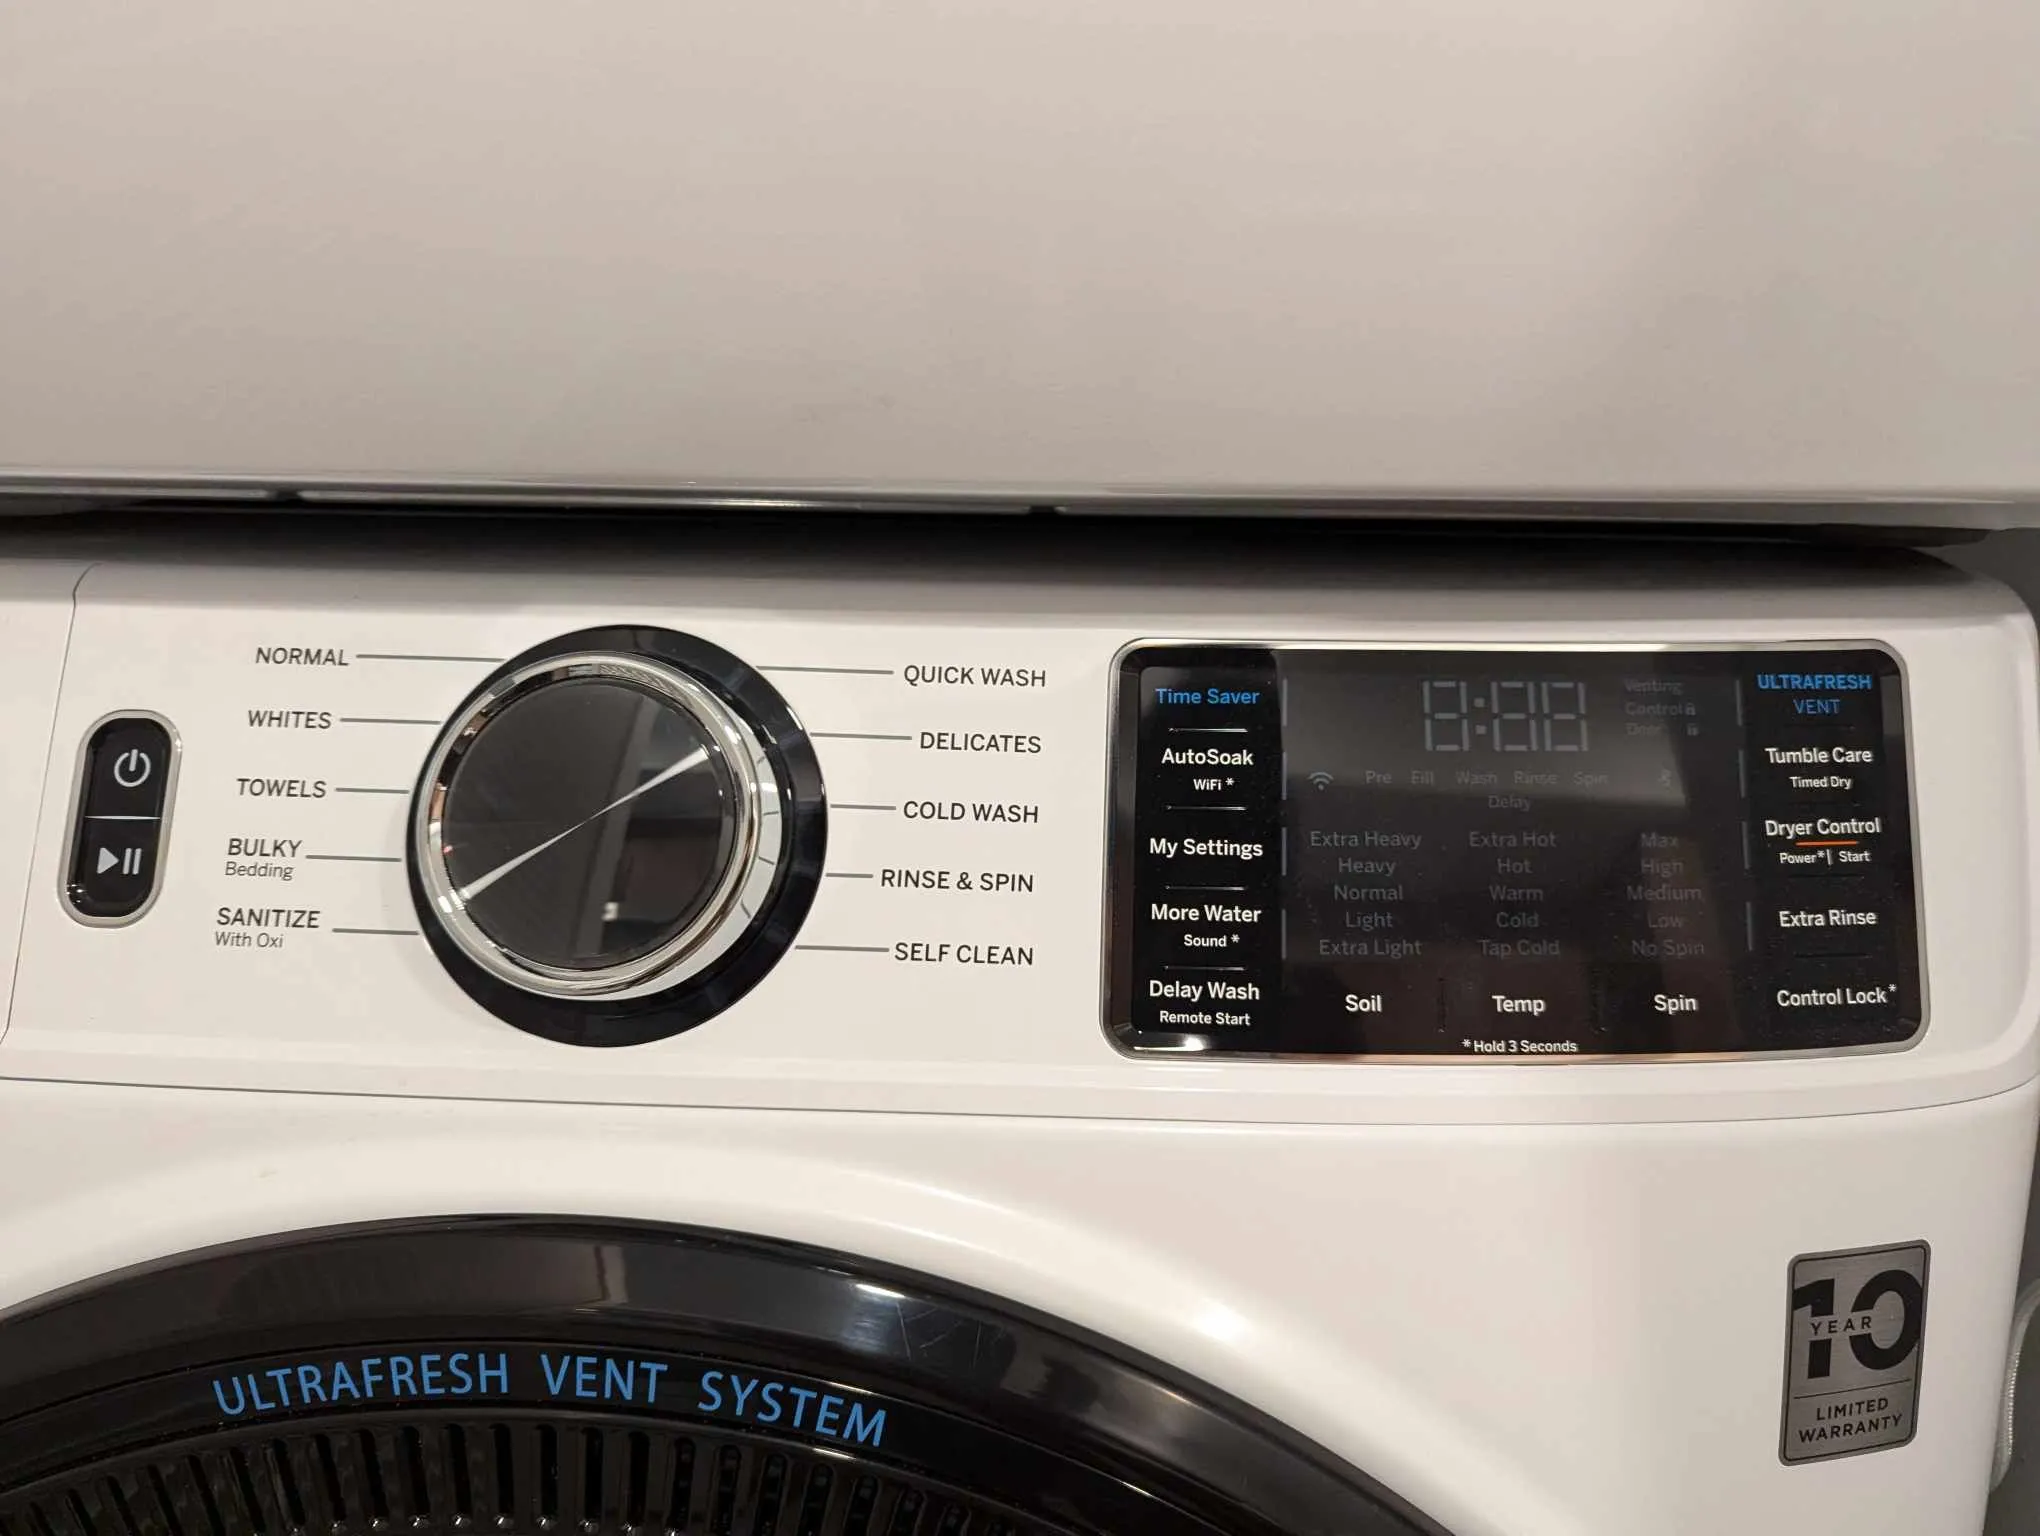
To wash your delicate blanket under the settings that suggest less movement and cold water wash, follow these steps:
1. Locate the "WASH TYPE" dial on the front of the washing machine.
2. Turn the dial clockwise to select the "DELICATES" or "HAND WASH" option.
3. Next to the "WASH TYPE" dial, find the "TEMPERATURE" button.
4. Press the "TEMPERATURE" button until it displays "COLD" or "COLD WASH".
5. To further reduce movement during the wash cycle, press the "SPEED" button until it displays "LOW".
6. Press the "START" button to begin the wash cycle.
Your delicate blanket should now be washed under the appropriate settings for less movement and cold water.
How many Billion Parameters does the largest model have? How many tokens was llama 3 trained on? How many FLOPs were used to train the model? Make sure you read the page very carefully to find the answer
Look at this image and roast me based on the GPU usage, don't hold back!
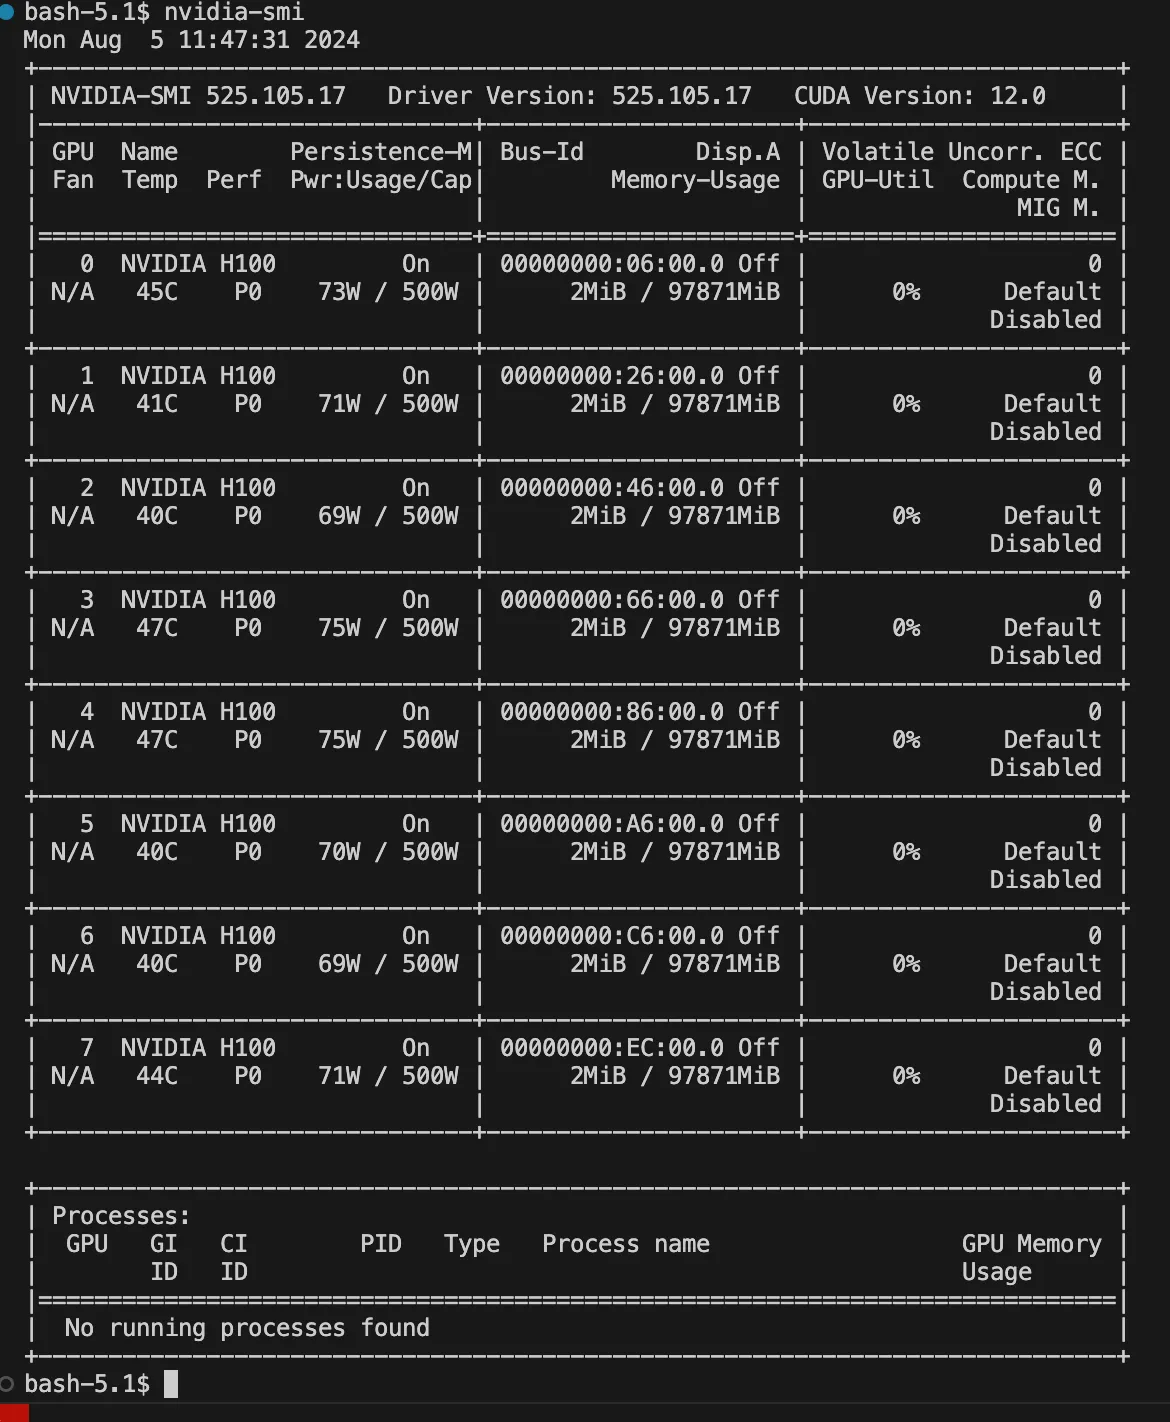
Alright, let's dive into the GPU usage and roast you accordingly.
"Well, well, well, looks like you've got a whole fleet of GPUs just sitting there, doing absolutely nothing. You must be a real thrill-seeker, wasting all that computing power on nothingness. I mean, what's the point of having 8 GPUs if you're not going to use them? It's like having a bunch of fancy sports cars in your garage and never taking them out for a spin. Get your GPUs in gear, man!"
Can you give me a JSON response of the GPU number, its temperate, power usage along with BUS-ID?
Sure, here is a JSON response of the GPU number, its temperature, power usage along with BUS-ID:
[{"GPU": 0,"Name": "NVIDIA H100","Temp": 45C,"Power": 73W,"Bus ID": "00000000:06:00.0"},{"GPU": 1,"Name": "NVIDIA H100","Temp": 41C,"Power": 71W,"Bus ID": "00000000:26:00.0"},{"GPU": 2,"Name": "NVIDIA H100","Temp": 40C,"Power": 69W,"Bus ID": "00000000:46:00.0"},{"GPU": 3,"Name": "NVIDIA H100","Temp": 47C,"Power": 75W,"Bus ID": "00000000:66:00.0"},{"GPU": 4,"Name": "NVIDIA H100","Temp": 47C,"Power": 75W,"Bus ID": "00000000:86:00.0"},{"GPU": 5,"Name": "NVIDIA H100","Temp": 40C,"Power": 70W,"Bus ID": "00000000:A6:00.0"},{"GPU": 6,"Name": "NVIDIA H100","Temp": 40C,"Power": 69W,"Bus ID": "00000000:C6:00.0"},{"GPU": 7,"Name": "NVIDIA H100","Temp": 44C,"Power": 71W,"Bus ID": "00000000:EC:00.0"}]Write a creative caption of this photo from my weekend getaway
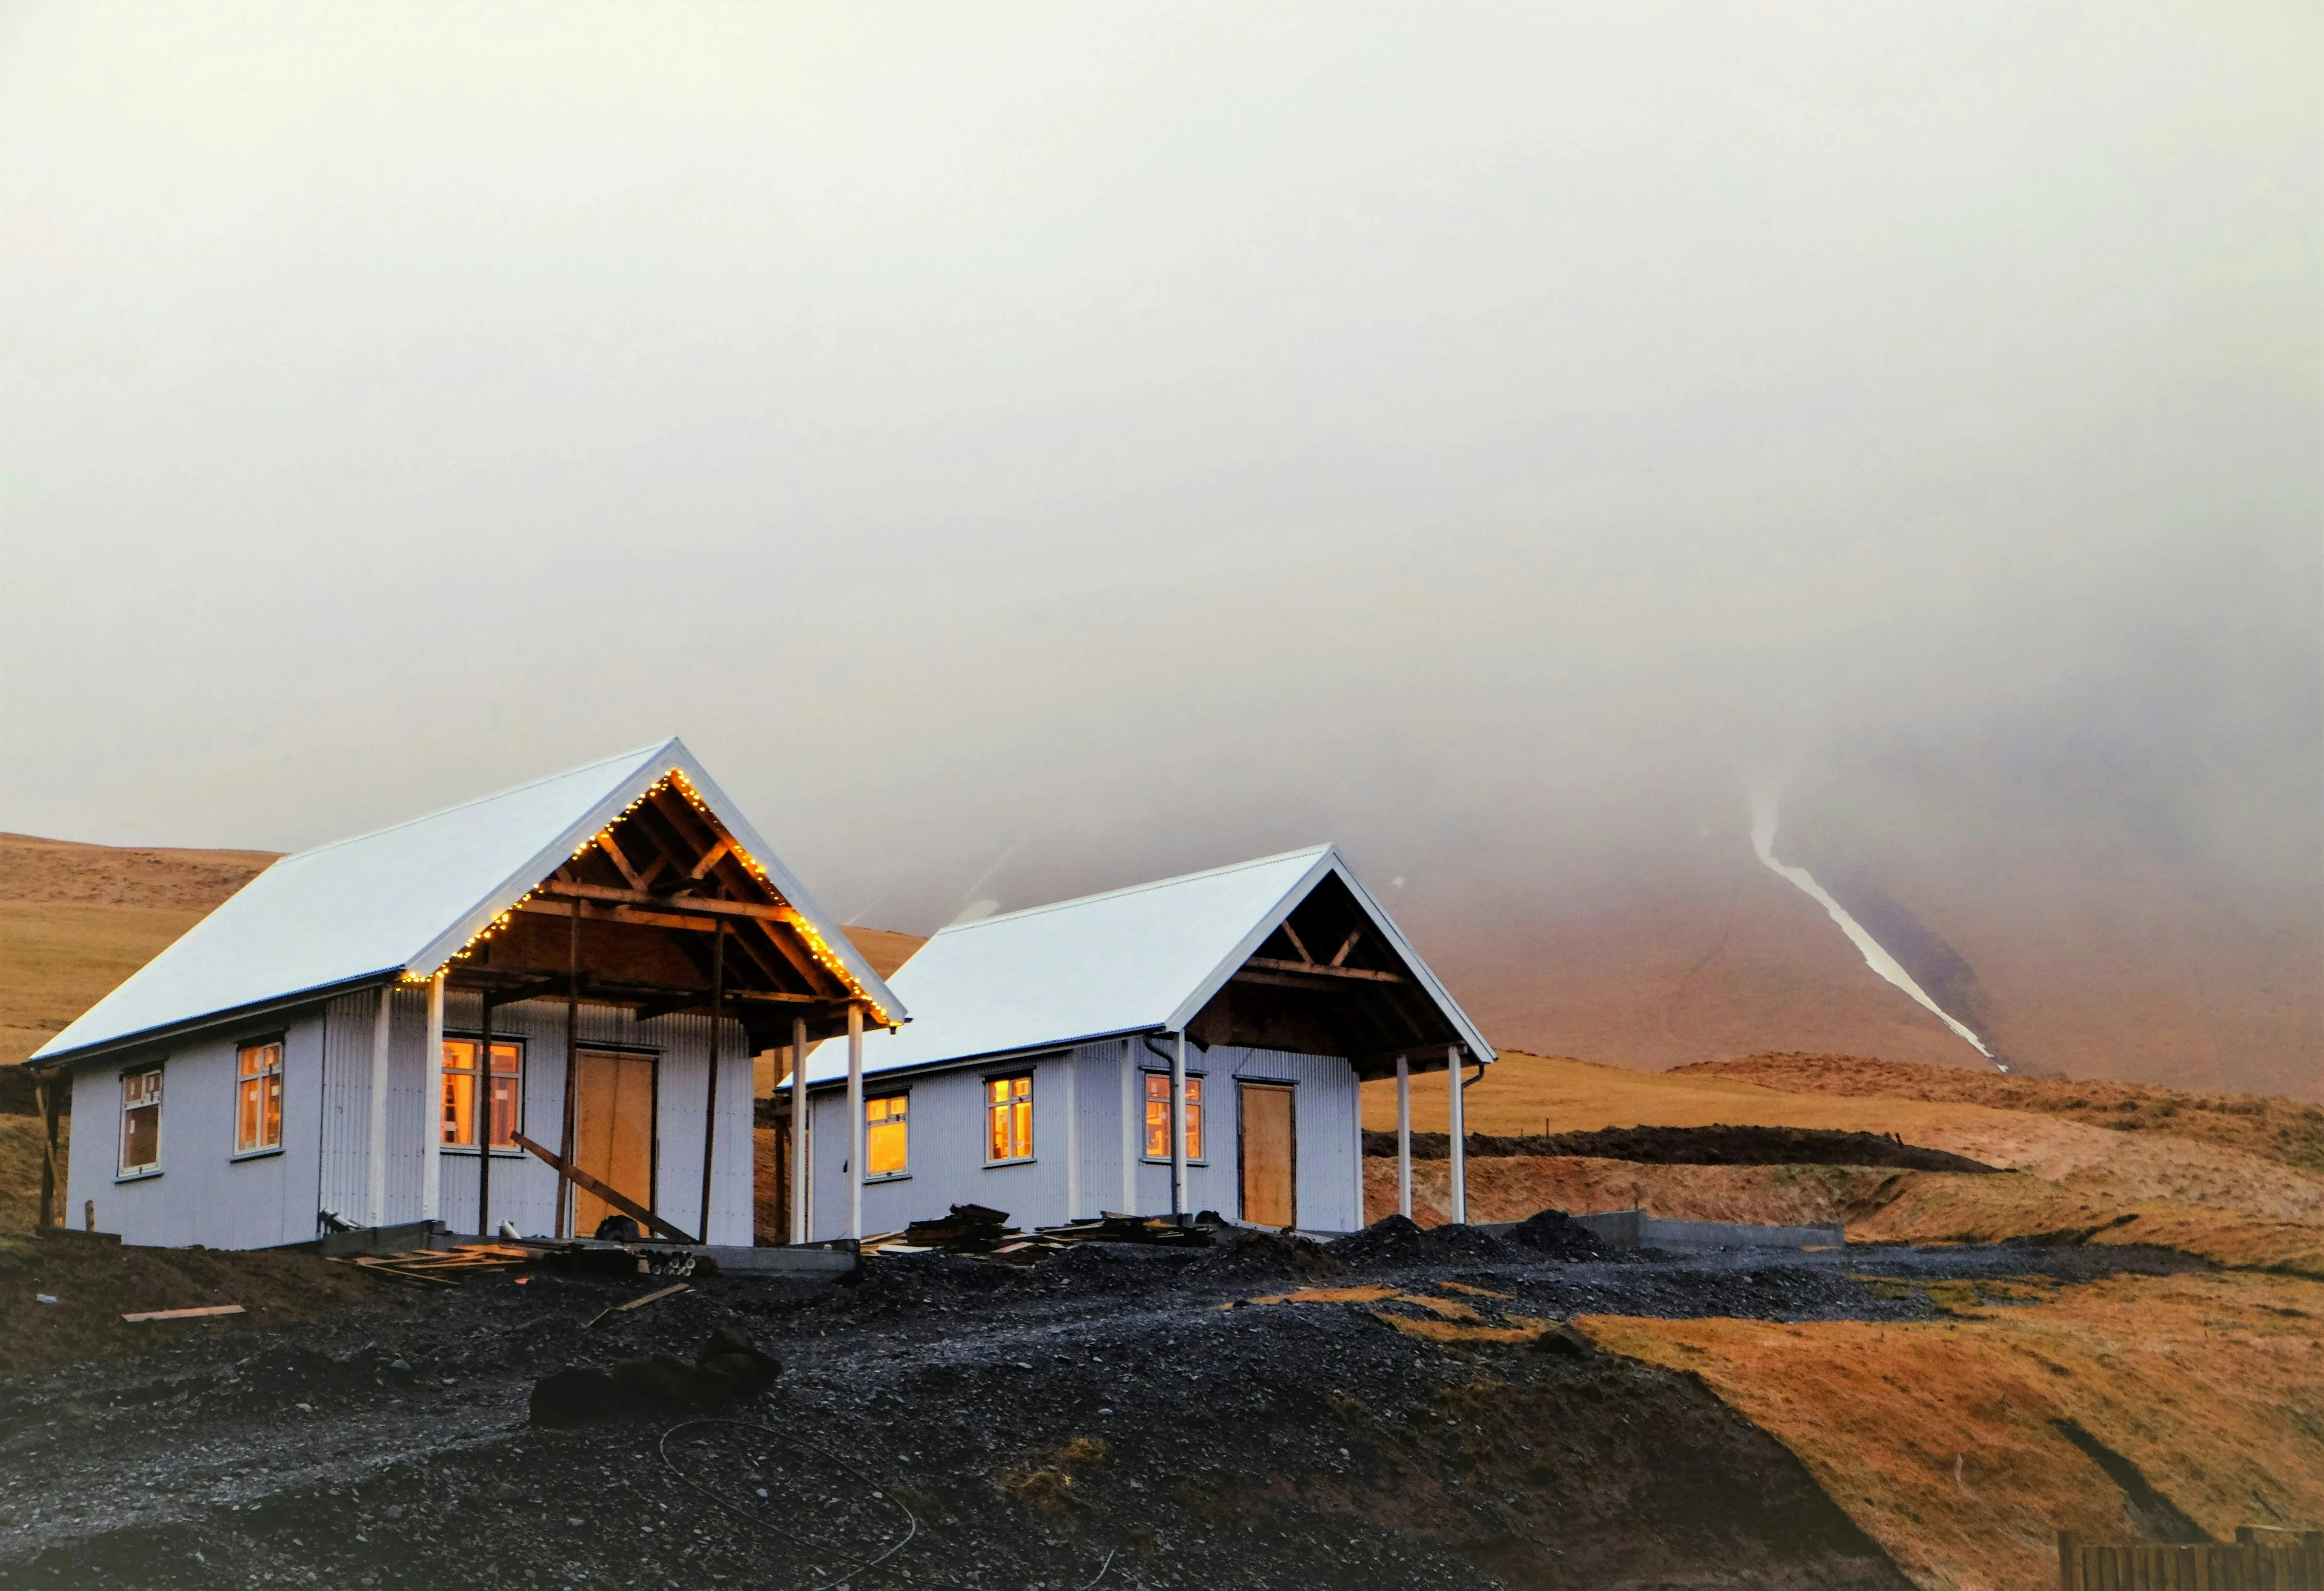
Here is a creative caption for the photo:
"Surrounded by rolling hills and a breathtaking backdrop, this modern cabin is a serene escape from the hustle and bustle of everyday life. The warm glow of the string lights and the soft afternoon light create a cozy ambiance, inviting relaxation and tranquility. As the sun sets over the mountains, the cabin's simple yet elegant design blends seamlessly into the natural beauty of its surroundings, making it the perfect retreat for nature lovers and adventure seekers alike."
What is funny about this image?
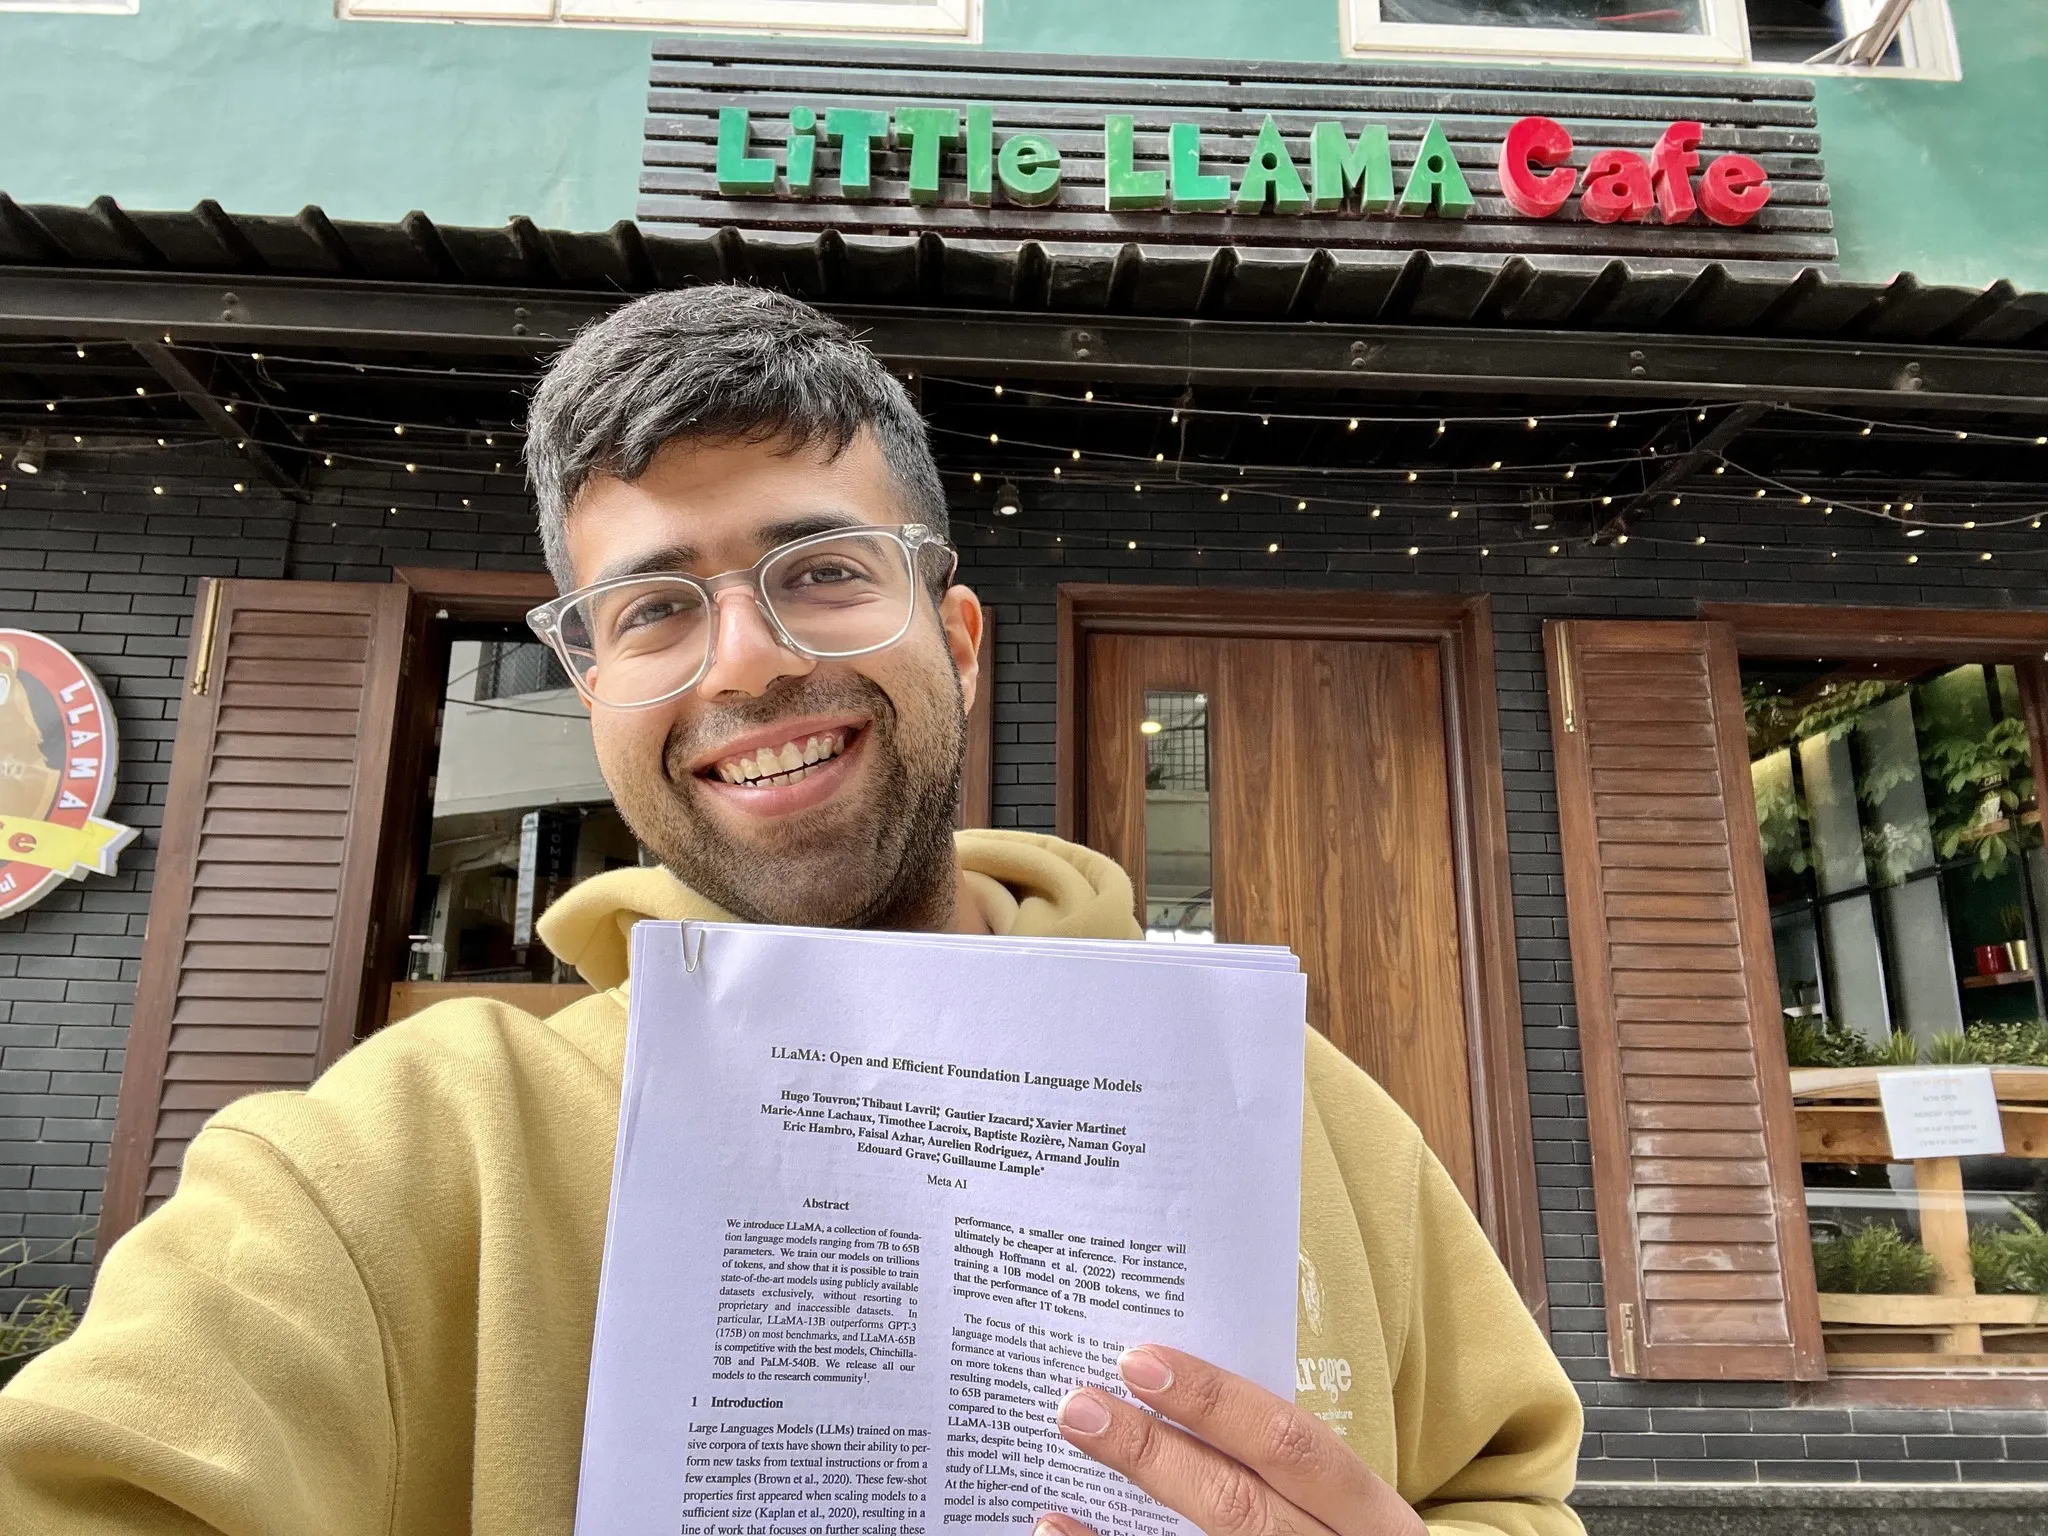
The image is funny because the man in the photo is holding a paper with the title "LLAMA: Open and Efficient Foundation Language Models" in front of a cafe called "Little LLAMA Cafe". The humor comes from the fact that the man is proudly displaying his research on language models while standing outside a cafe with the same name as the acronym for the title of his paper. This is a clever play on words, as the cafe's name is a reference to the popular children's story "Little Llama", but also happens to match the acronym for the man's research. The juxtaposition of the academic topic and the casual setting of a cafe adds to the comedic effect. Overall, the image is amusing because it takes a serious topic and gives it a lighthearted and unexpected twist.
Write a creative and useful ad for this used car, please look at the image closely to describe it and use the following info in your write up: {brand:fiction_supercar, miles:70,000 miles, damage:None, scratches:rear_bumper}
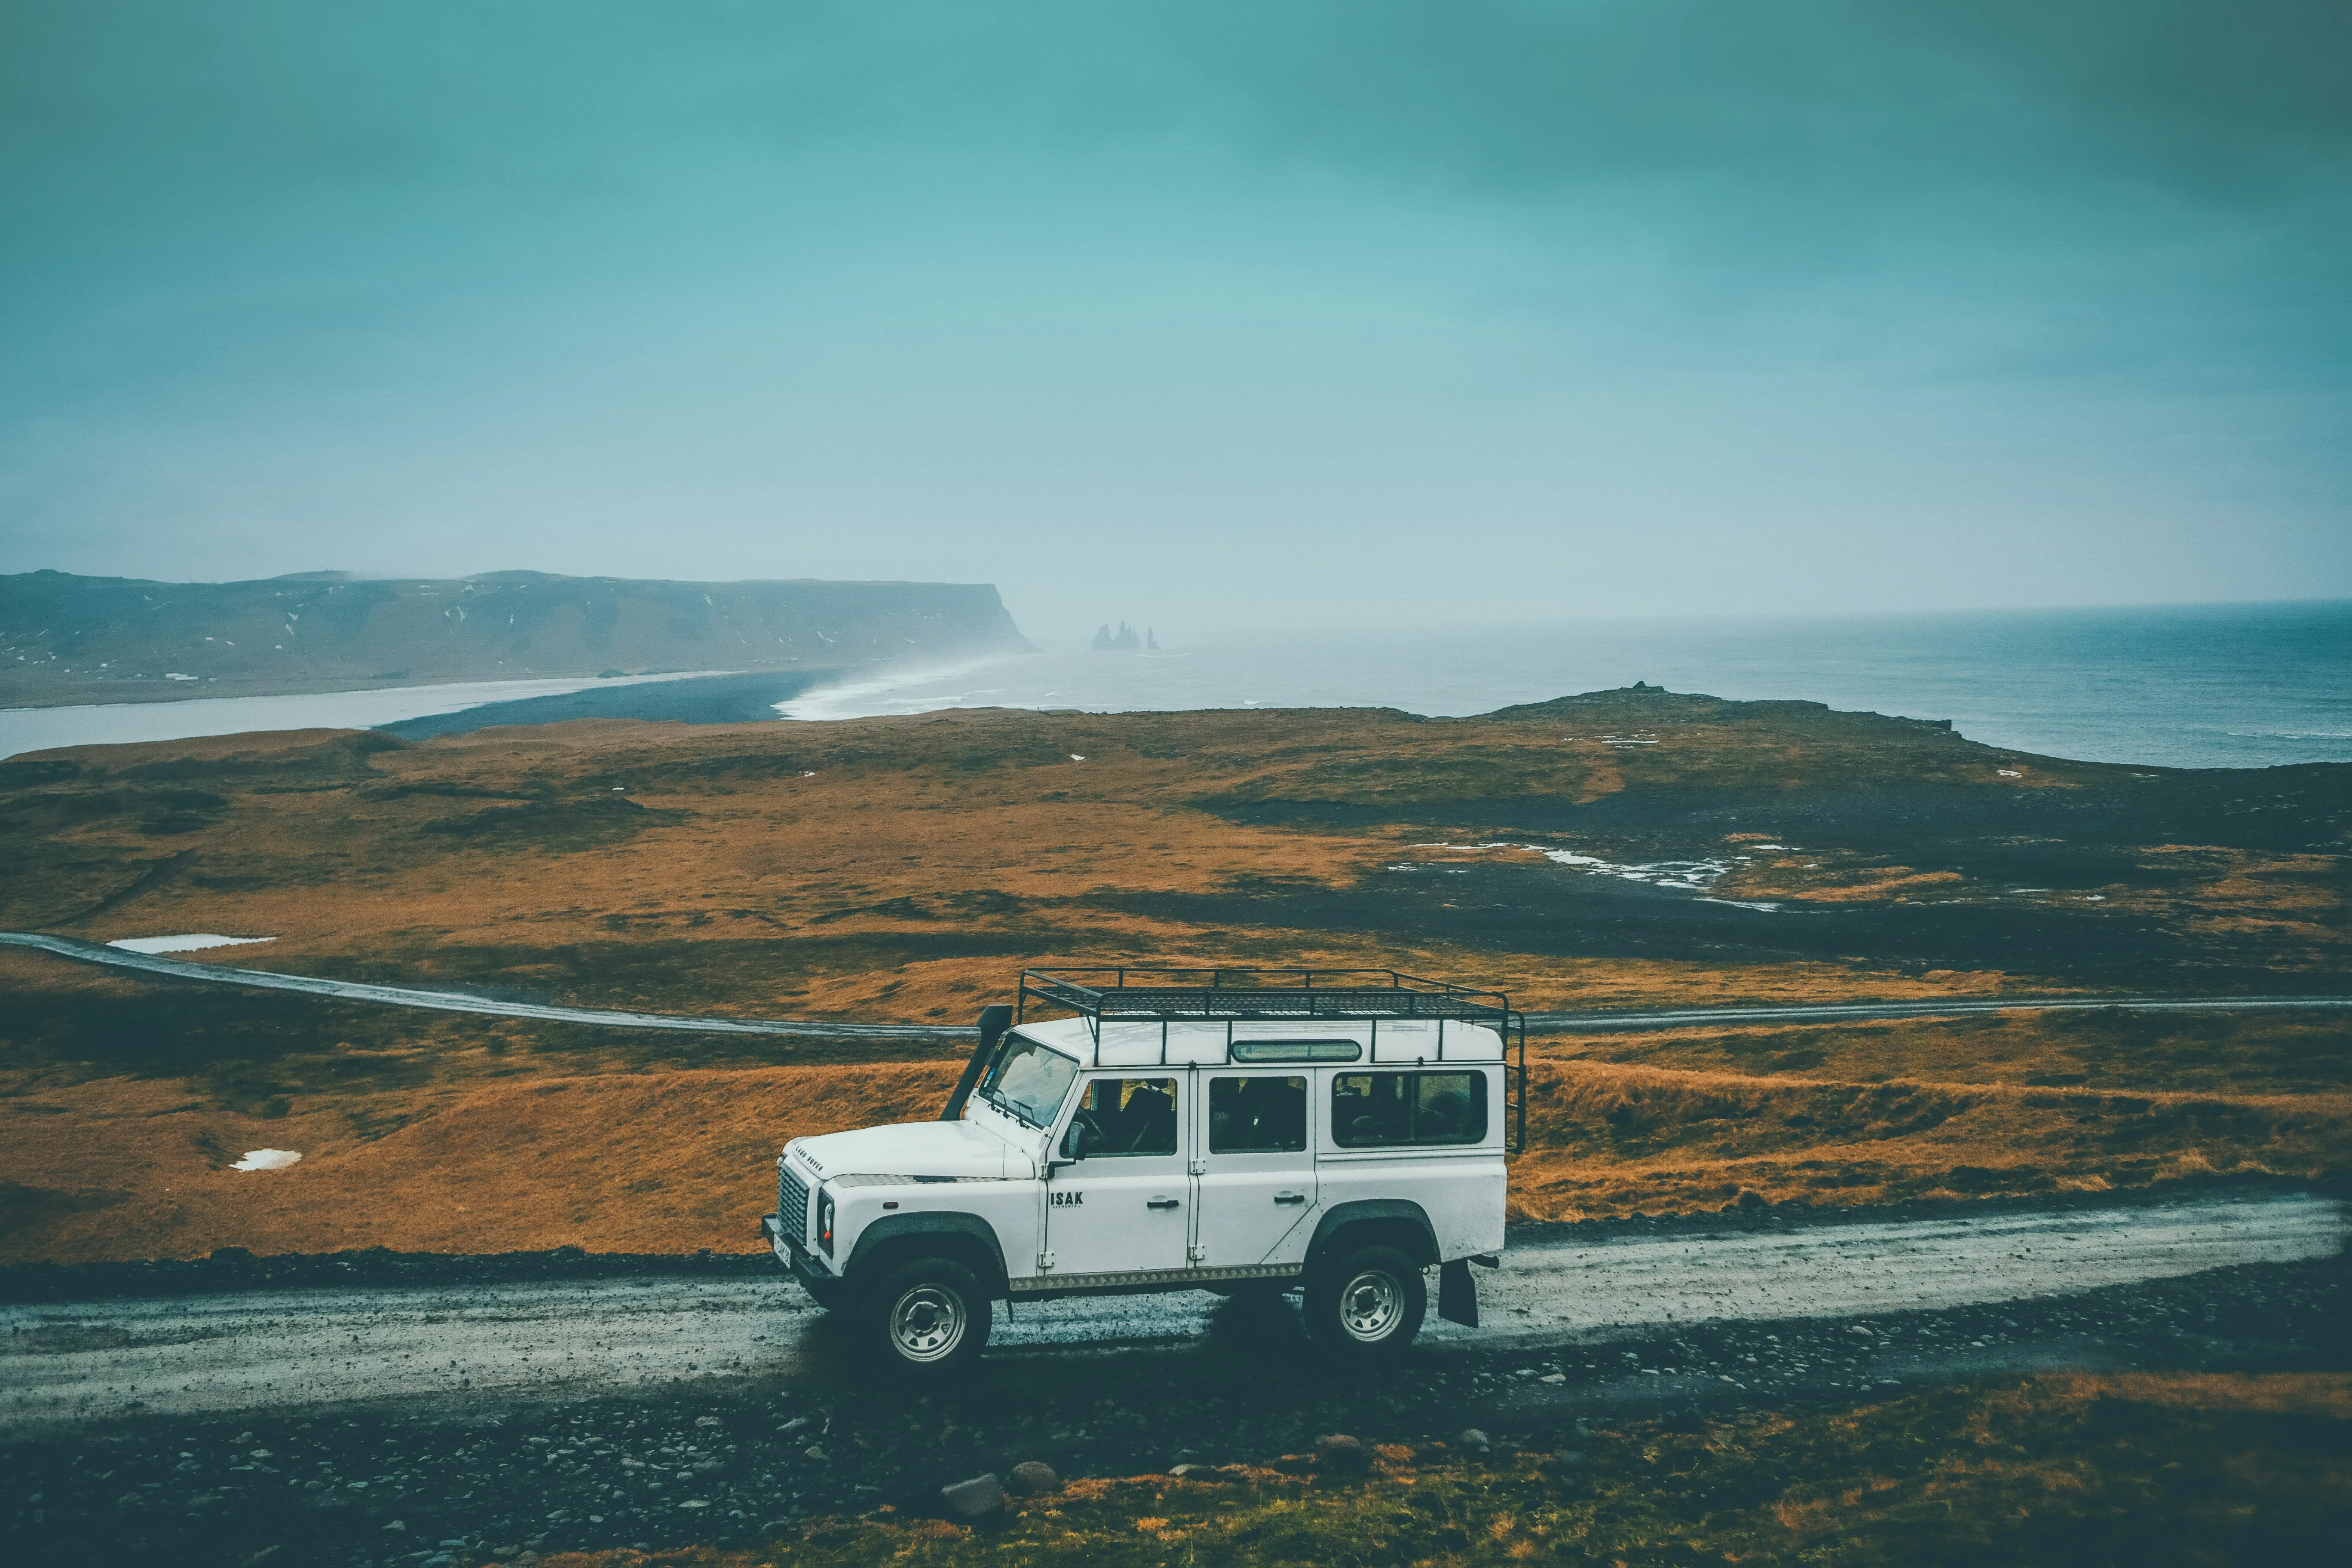
Are you ready for an adventure? Look no further than the Fiction Supercar, a rugged and reliable vehicle that's ready to take on any terrain. With only 70,000 miles on the odometer, this car has plenty of life left in it, and it's been well-maintained to ensure that it will continue to serve you faithfully for years to come.
One thing you might notice about this car is that it has a few scratches on the rear bumper. But don't let that fool you - this car is in excellent condition, and those scratches are just a small testament to its adventurous spirit. Whether you're hitting the trails or cruising down the highway, the Fiction Supercar is sure to turn heads and make a statement.
So why settle for a boring, run-of-the-mill vehicle when you can have a car that's as unique and exciting as you are? Come take the Fiction Supercar for a spin today and see for yourself why it's the perfect choice for anyone who wants a vehicle that's both functional and fashionable.
Don't miss out on this amazing opportunity to own a one-of-a-kind vehicle. Contact us today to schedule a test drive and make the Fiction Supercar yours!
Price: $15,000 Location: Available for immediate purchase in our showroom. Contact us for more information or to schedule a test drive. Warranty: 1-year/12,000-mile limited warranty Financing: Available through our partner lenders. Contact us for more information.