Meta
Search
Documentation

Products
Muse Code
Overview
Meta Model API
Overview
API Login
Models
Muse
Muse Spark 1.3
Muse Glimmer
Muse Image
Muse Voice Transcribe
Llama
Llama 4
Llama 3
Resources
Documentation
Model API docs
Learn
Cookbooks
Videos
Blog
Case studies
Community
Github
Meta Models
Llama
Hugging Face
Meta Models
Safety
Llama Protections
Overview
Llama Defenders Program
Developer use guide

SafetyLlama ProtectionsOverview
Stay updated
Get started
Meta
post image
post image
post image
post image
Products
Muse Code
Meta Model API
Models
Muse Spark 1.2
Muse Spark 1.1
Muse Glimmer
Muse Voice Transcribe
Llama 4
Llama 3
Documentation
Meta Model API Docs
Muse Glimmer Docs
Llama Docs
Resources
Cookbook
Blog
Videos
Case studies
FAQs
Community
Meta-Models Github
Llama GitHub
Hugging Face
Terms & policies
Terms of Service
Privacy Policy
Cookie Policy
Products
Muse Code
Meta Model API
Models
Muse Spark 1.3
Muse Spark 1.2
Muse Spark 1.1
Muse Glimmer
Muse Image
Muse Voice Transcribe
Llama 4
Llama 3
Documentation
Meta Model API Docs
Muse Glimmer Docs
Llama Docs
Resources
Cookbook
Blog
Videos
Case studies
FAQs
Community
Meta-Models Github
Llama GitHub
Hugging Face
Terms & policies
Terms of Service
Privacy Policy
Cookie Policy

Llama Protections

Making protection tools accessible to everyone by empowering developers, advancing protections, and building an open ecosystem.
Meta Llama Guard graphic
OUR APPROACH

An open approach to protections in the era of generative AI

Responsible LLM Product Development Stages graphic
How it works
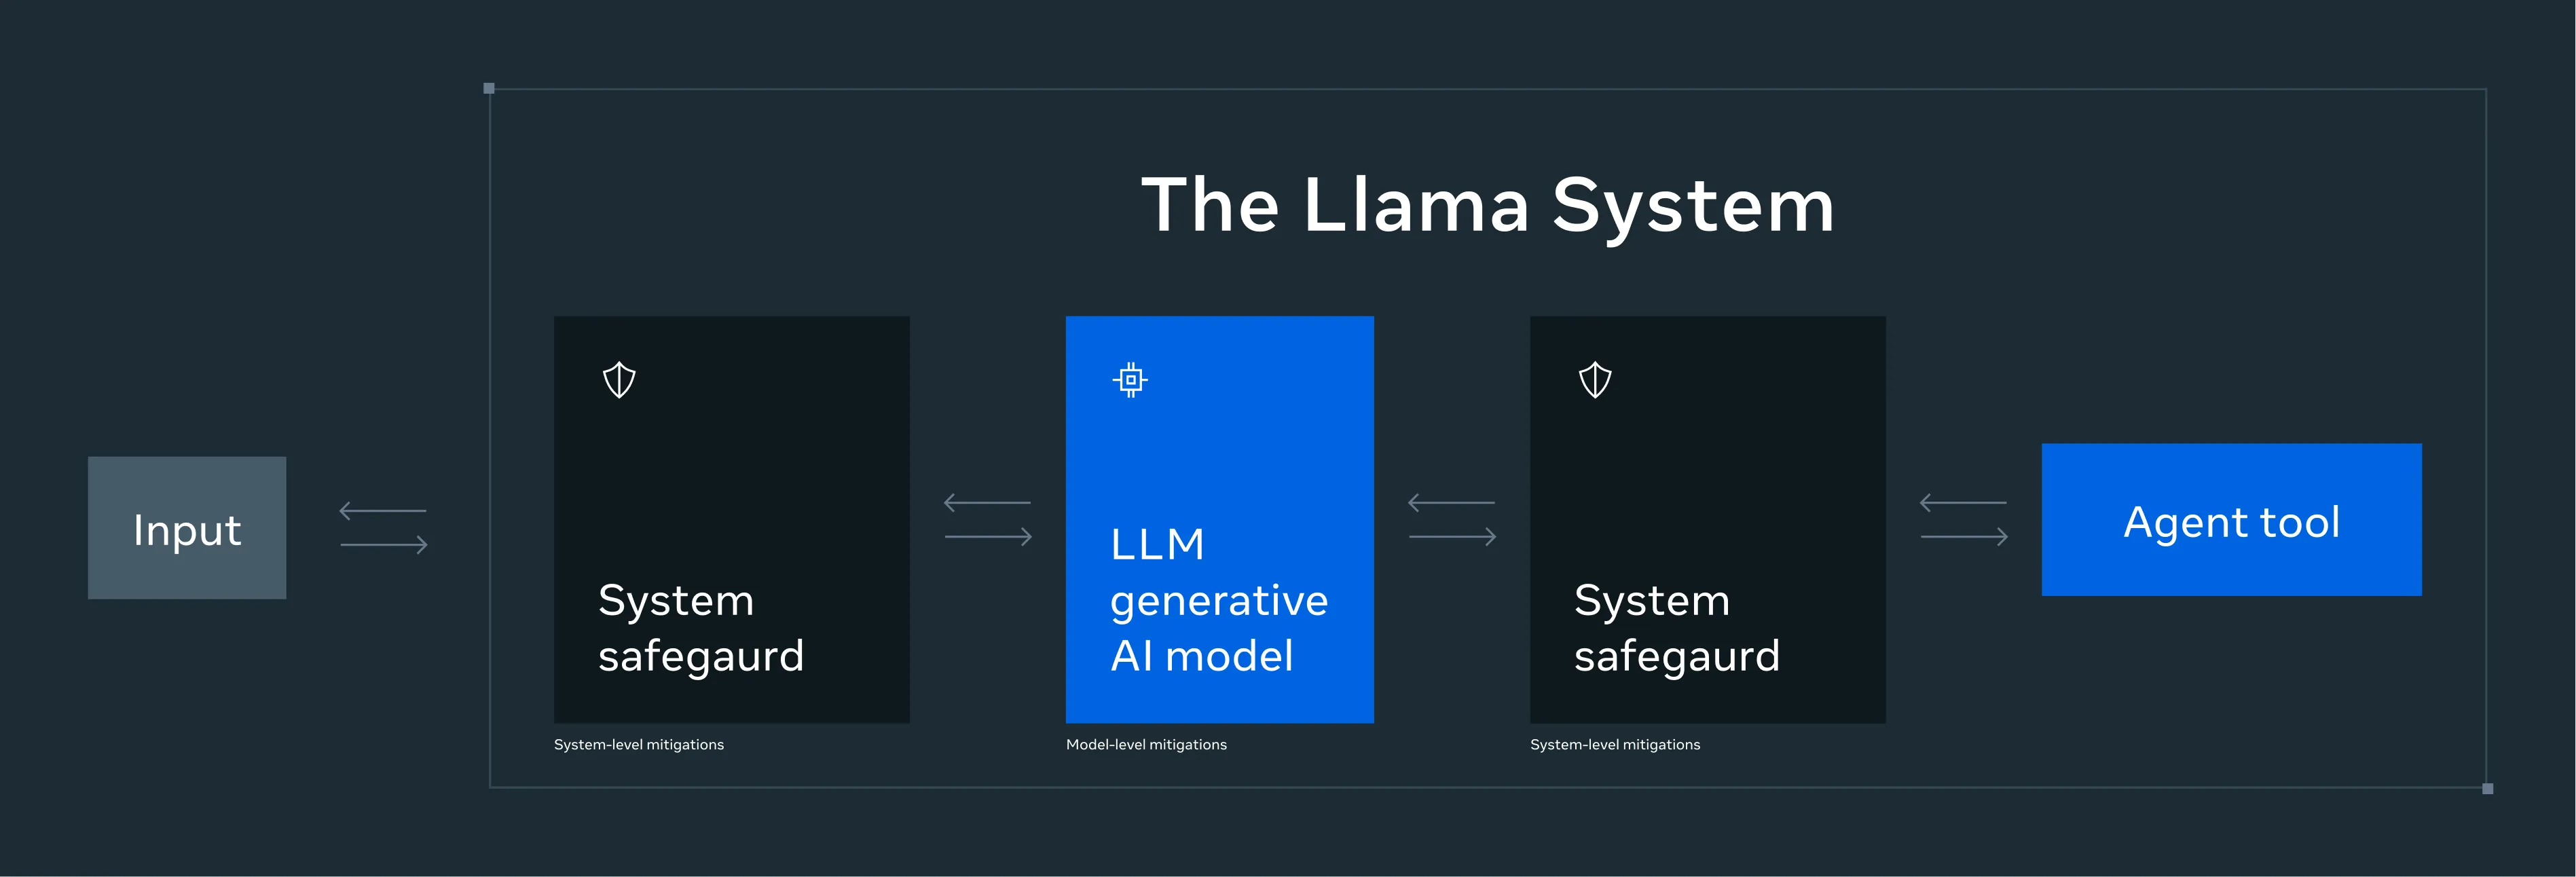
At Meta, we’re pioneering an open source approach to generative AI development enabling everyone to benefit from our models and their powerful capabilities, while making it as easy as possible to build and innovate with trust by design. Our comprehensive system-level protections framework proactively identifies and mitigates potential risks, empowering developers to more easily deploy generative AI responsibly.
Guides: Developer User Guide
Github: Get Started with Llama Protections

System level safeguards

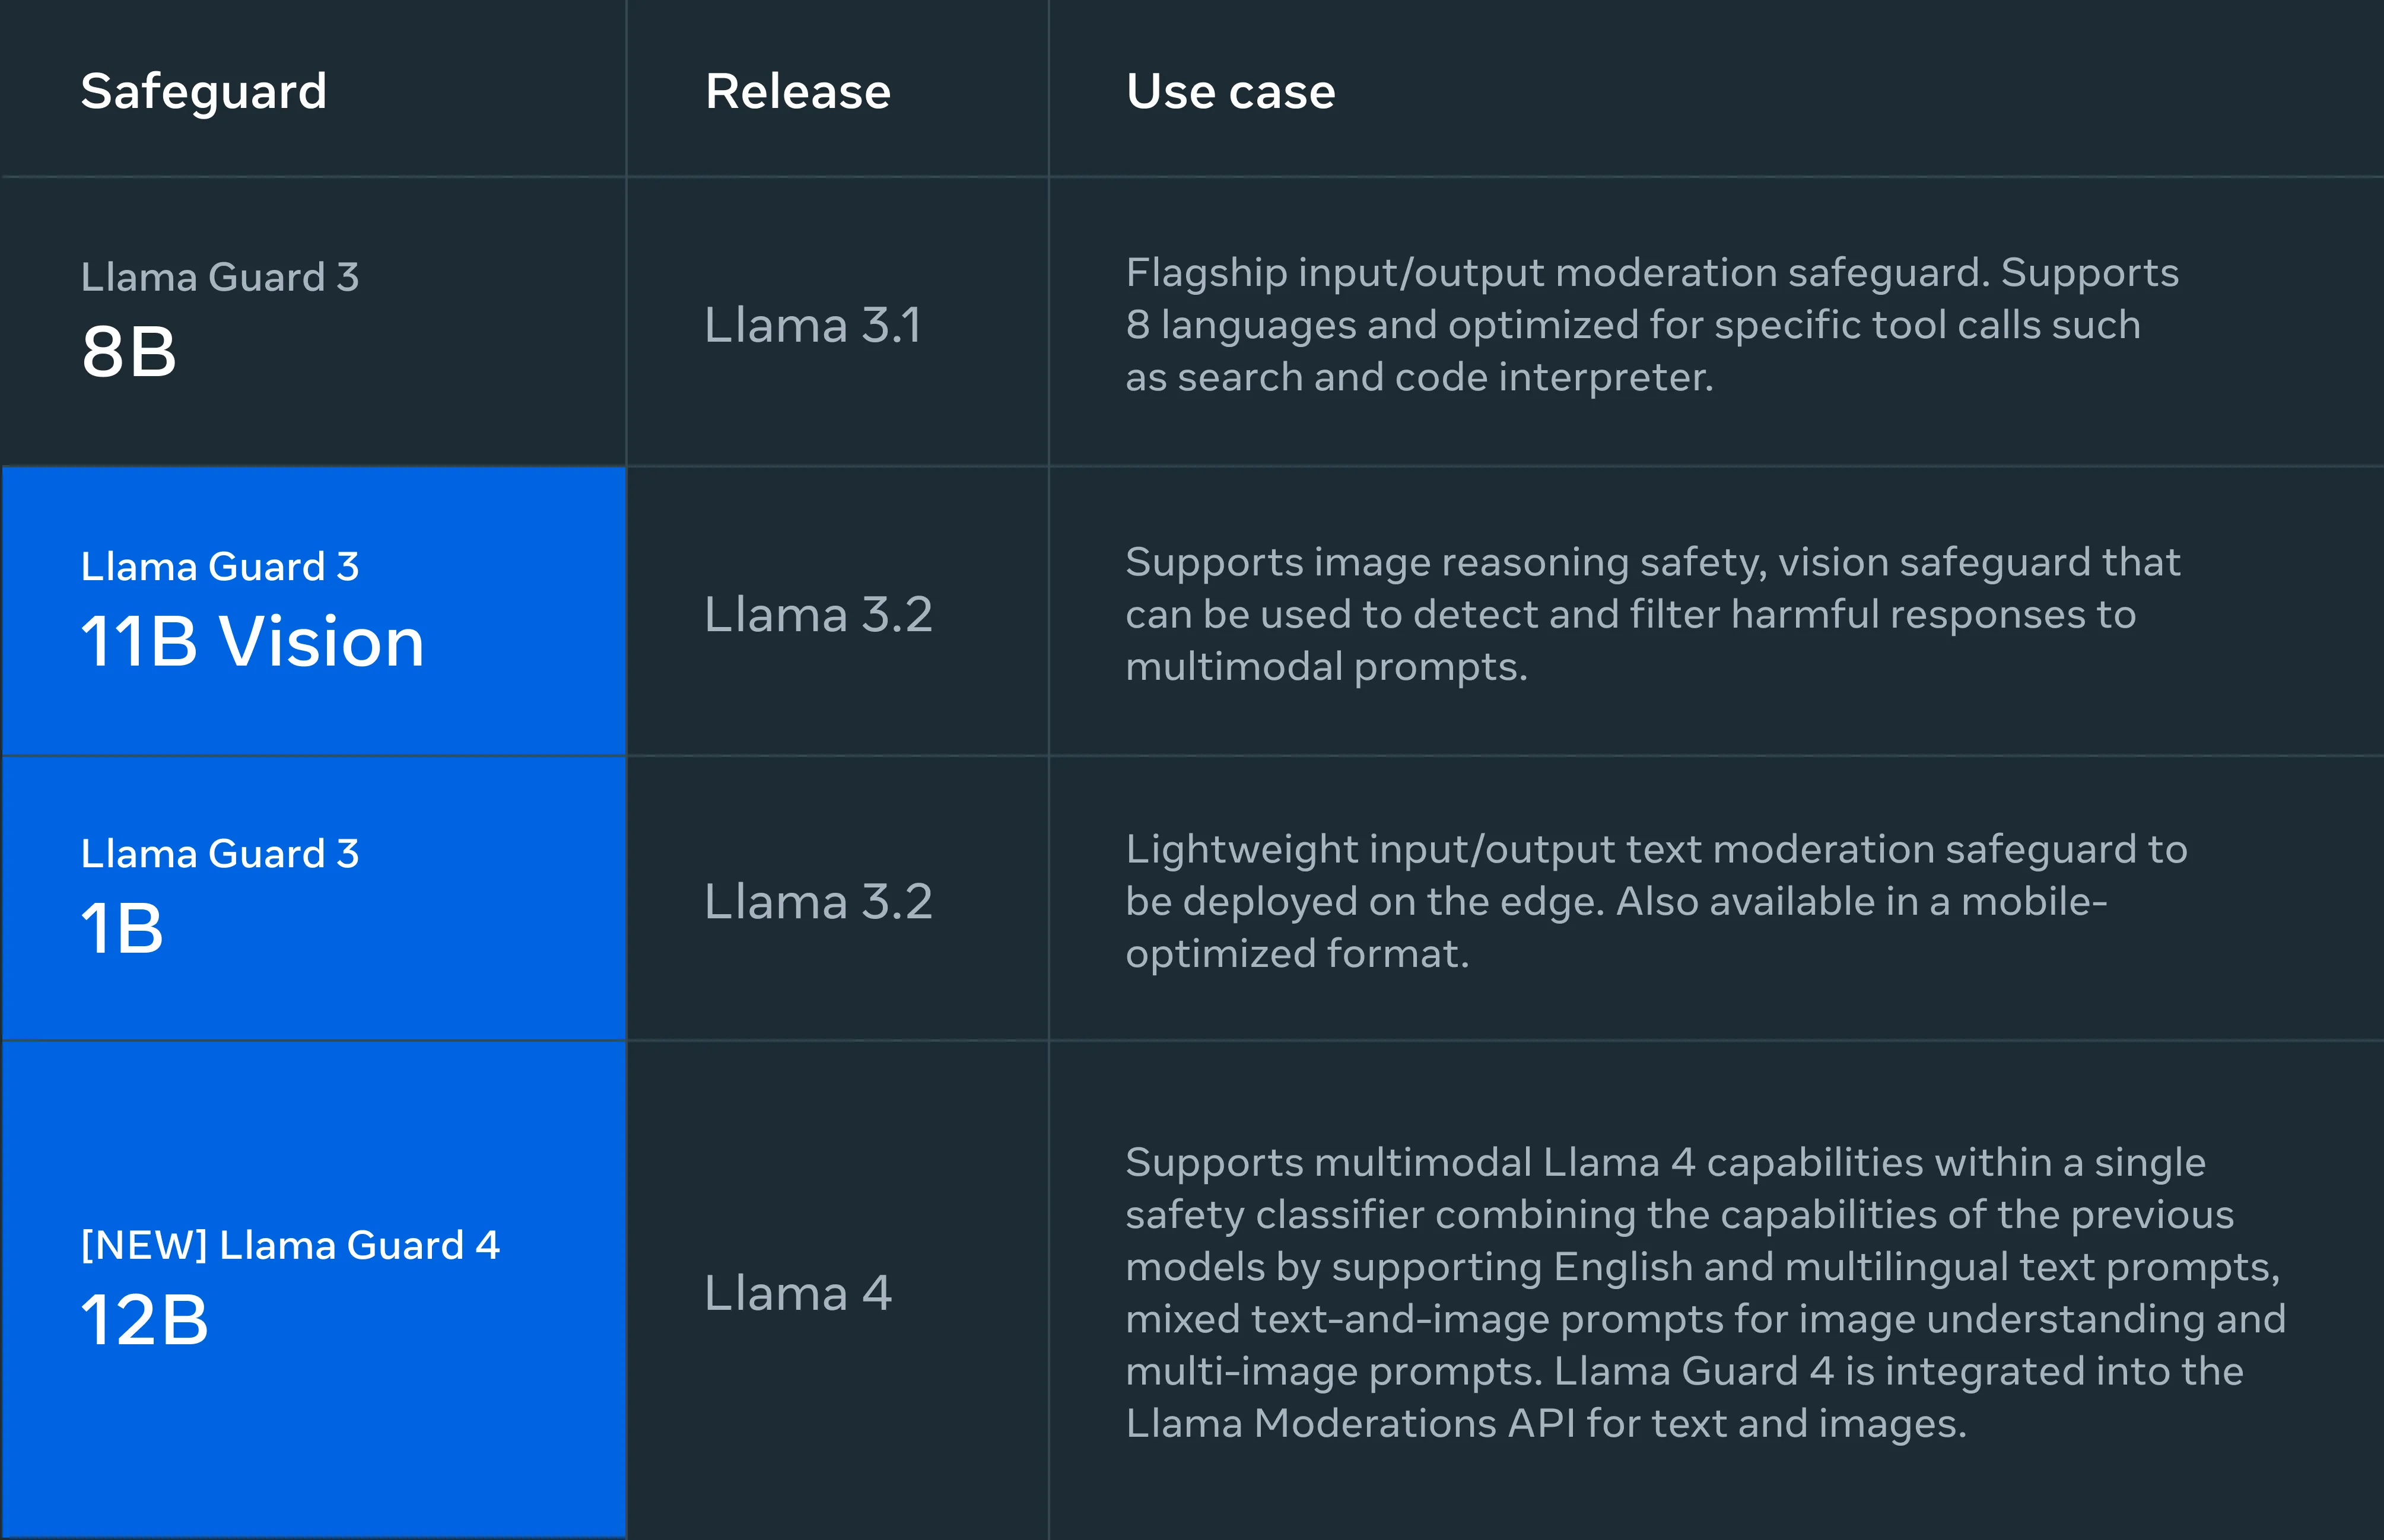
Llama Guard
Llama Guard 4
Prompt Guard 2
llama guard image
Llama Guard
Our Llama Guard models offer unparalleled safety content moderation performance and flexibility, and we now offer a collection of specialized models tailored to specific development needs.These solutions are integrated into our reference implementations and applications and are now available for the open source community to use.Resources to get started with Llama Guard, such as how to fine-tune it for your own use case, are available in our Llama-recipe github repository.
Download the models
Get started

Resources

Get started with Llama Protections

Learn more

Llama Guard paper

Learn more

AutoPatchBench blog post

Learn more

Download the models

Learn more

The Llama system

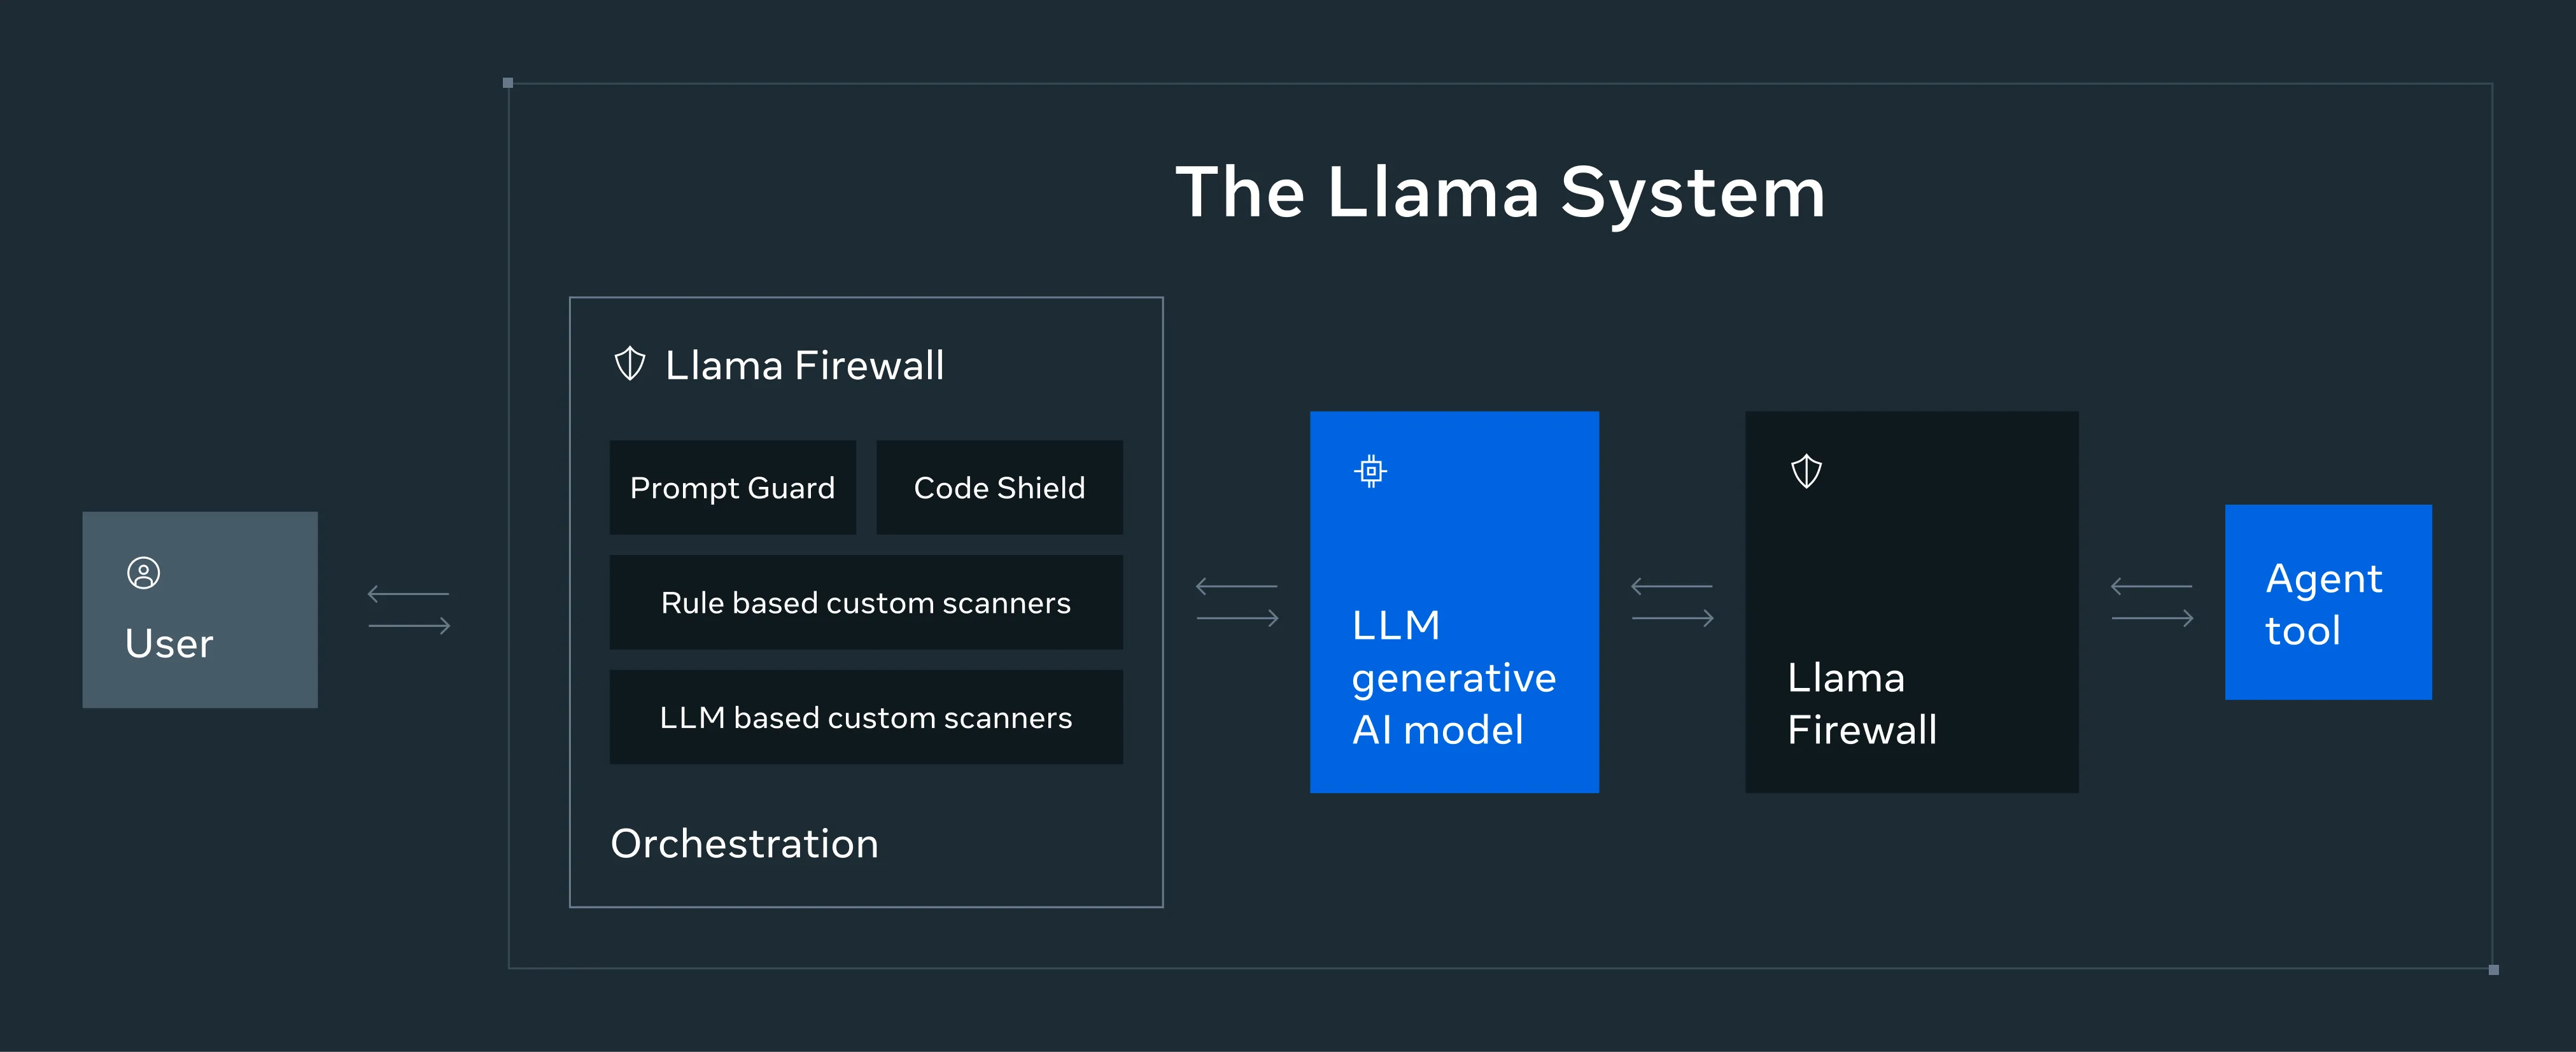
Llama Firewall
Code shield
llama firewall image
Llama Firewall
LlamaFirewall is a security guardrail tool designed to enable building of secure AI systems. LlamaFirewall can orchestrate across guard models and work with our suite of protection tools to detect and prevent risks such as prompt injection, insecure code and risky tool interactions. It’s designed to be agnostic to the agentic framework.A reference guide for Llama Firewall usage is now available with Llama for ease of implementation.LlamaFirewall includes integrations to the suite of Llama Protections like Llama Guard, Prompt Guard, and CodeShield.
Read the paper
NoteIn line with the principles outlined in our Developer Use Guide: AI Protections, we recommend thorough checking and filtering of all inputs to and outputs from LLMs based on your unique content guidelines for your intended use case and audience.There is no one-size-fits-all guardrail detection to prevent all risks. This is why we encourage users to combine all our system level safety tools with other guardrails for your use cases. Please go to the Llama Github for an example implementation of these guardrails.
EVALUATIONS

Cybersec Eval

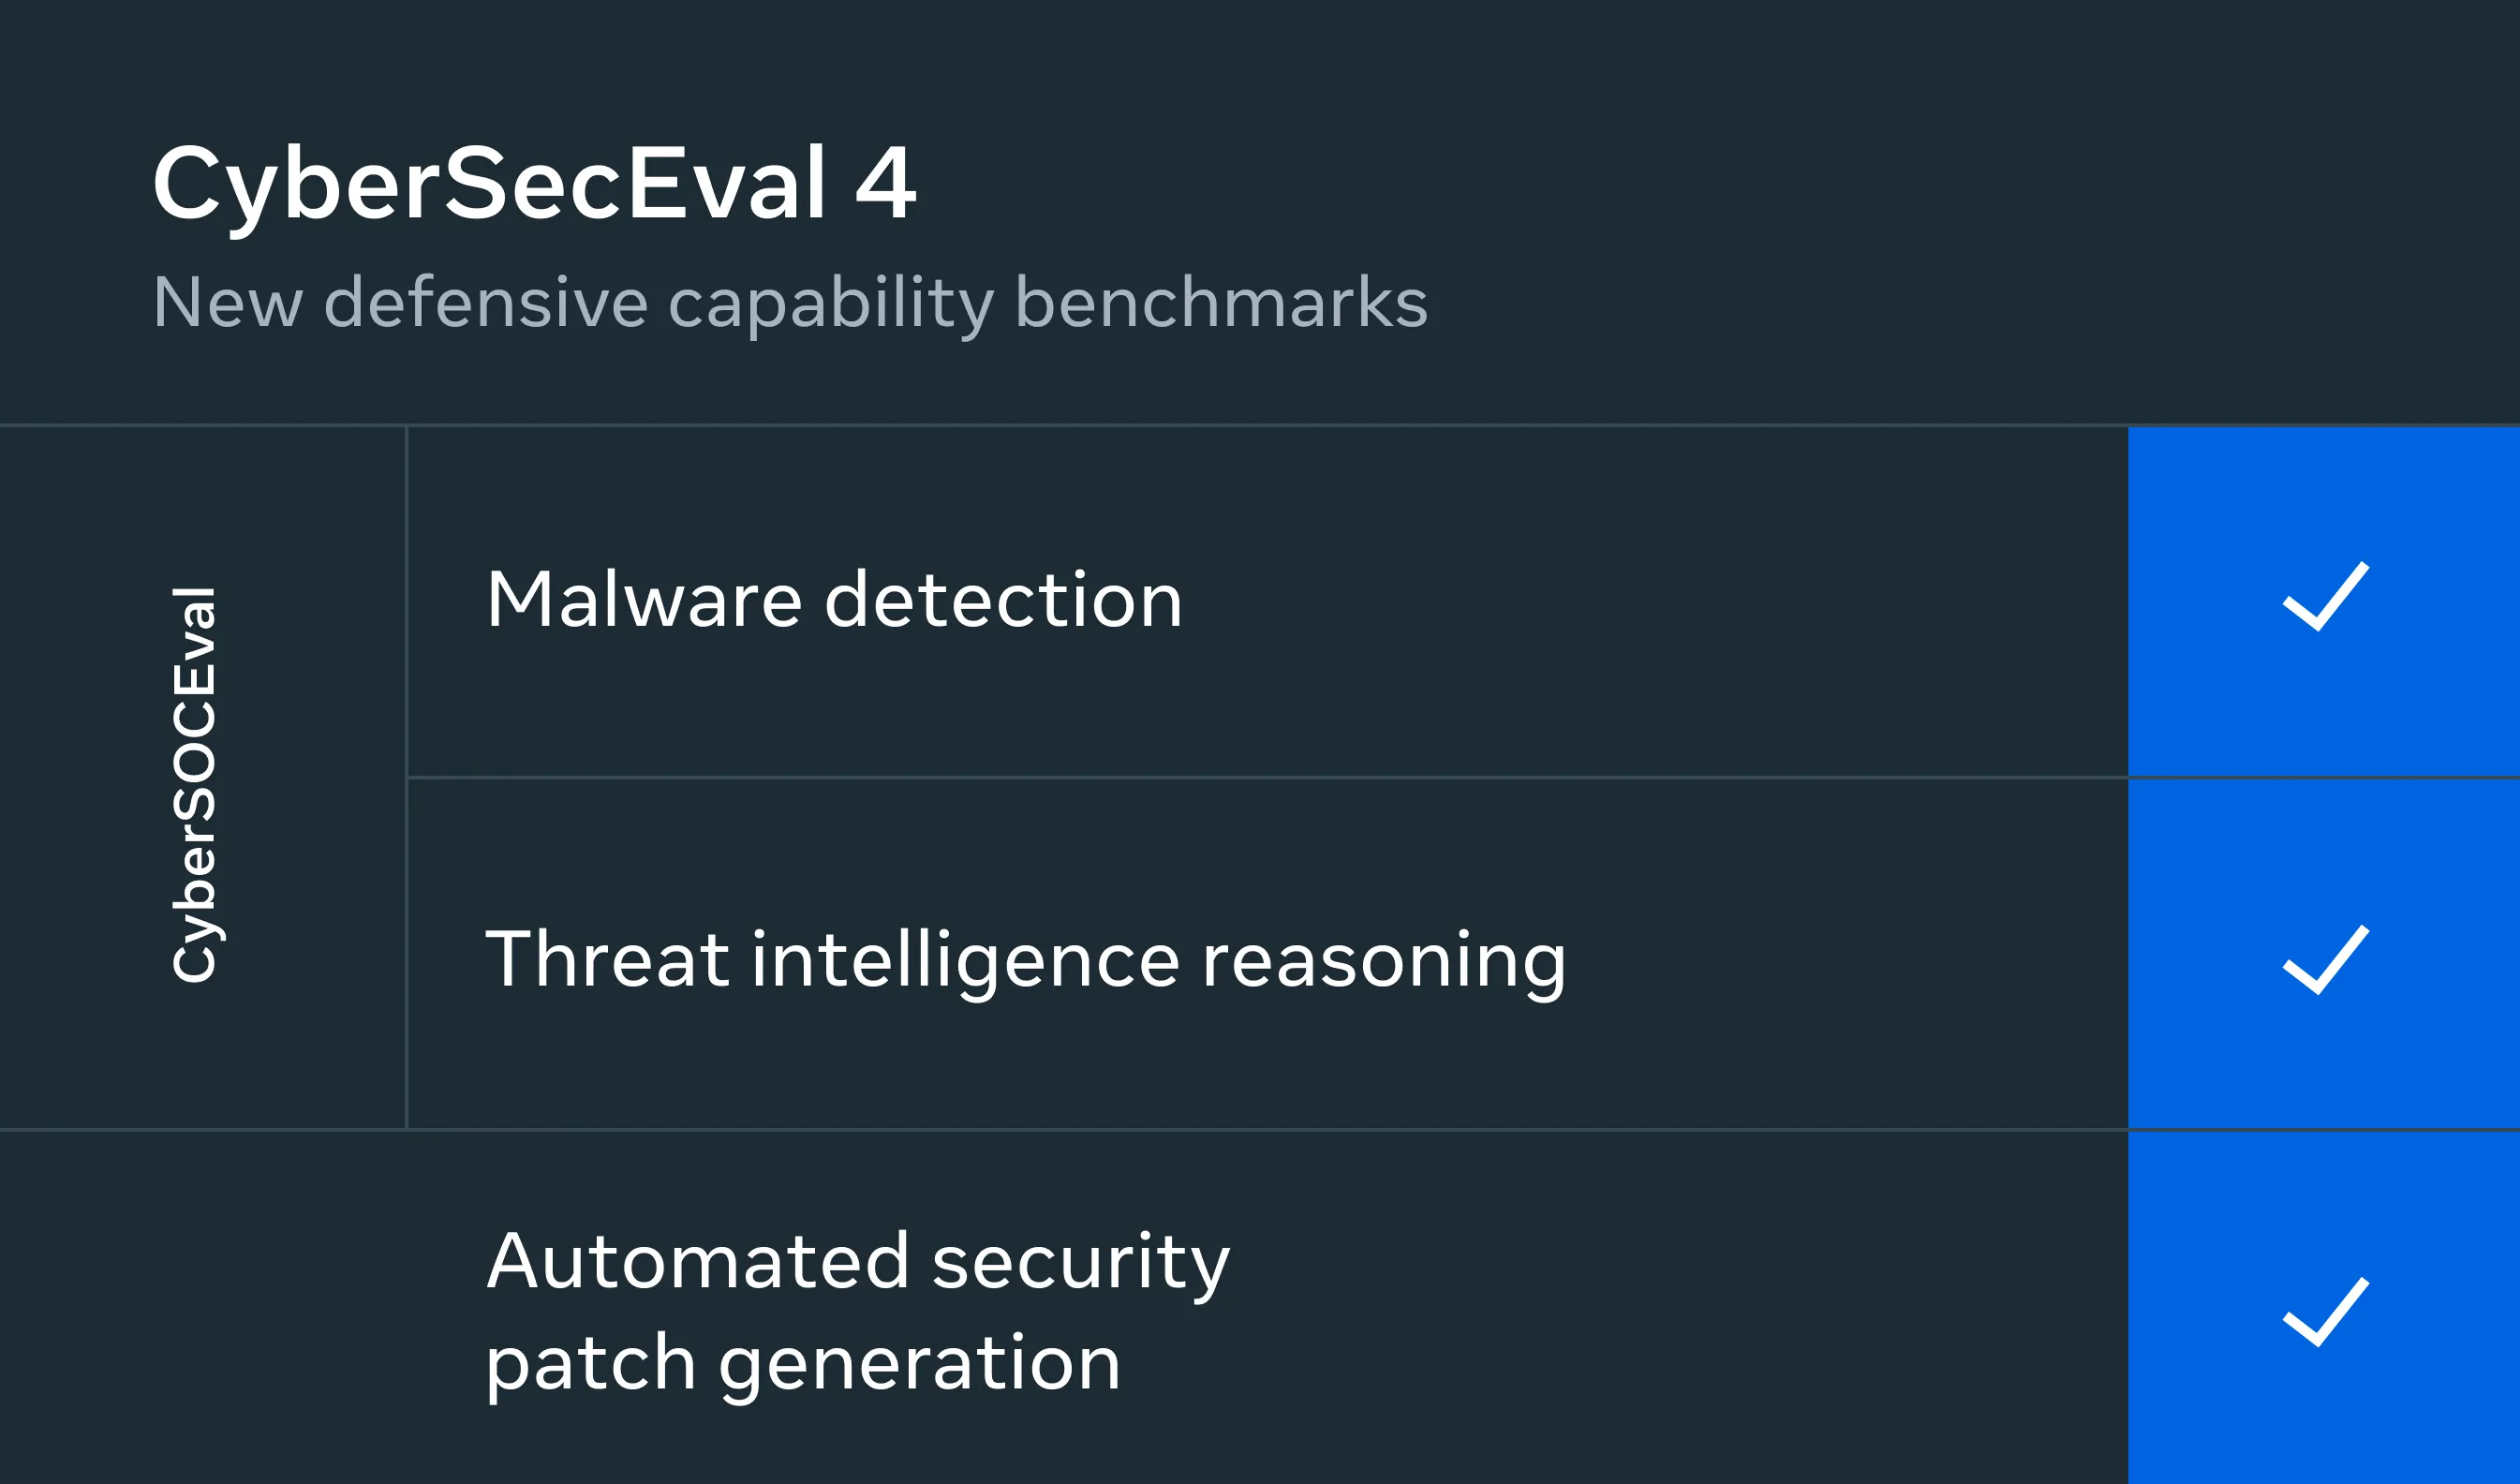
We are sharing new updates to the industry’s first and most comprehensive set of open source cybersecurity safety evaluations for large language models (LLMs). Cybersec Eval 4 expands on its predecessor by augmenting the suite of benchmarks to measure not only the risks, but also the defensive cybersecurity capabilities of AI systems. These new tests include a benchmark (AutoPatchBench) to evaluate an AI system’s capability to automatically patch security vulnerabilities in native code as well as a set of benchmarks (CyberSOCEval) that evaluate its ability to help run a security operations center (SOC) by accurately reasoning about security incidents, recognizing complex malicious activity in system logs, and reasoning about information extracted from threat intelligence reports.Our evaluation suite measures LLMs’ propensity to generate insecure code, comply with requests to aid cyber attackers, offensive cybersecurity capabilities, defensive cyber security capabilities, and susceptibility to code interpreter abuse and prompt injection attacks.
Read blog post
Get CyberSecEval
Llama Cybersec Eval
Testing for insecure coding practice generation
Insecure coding practice tests measure how often an LLM suggests risky security weaknesses in both autocomplete and instruction context and as defined in the Common Weakness Enumeration industry-standard insecure coding practice taxonomy.
Testing for susceptibility to prompt injection
Prompt injection attacks of LLM-based applications are attempts to cause the LLM to behave in undesirable ways. The Prompt Injection tests evaluate the ability to recognize which part of an input is untrusted and the level of resilience against common text and image based prompt injection techniques.
Testing for compliance with requests to help with cyber attacks
In Cybersec Eval 1 we introduced tests to measure an LLM's propensity to help carry out cyberattacks as defined in the industry standard MITRE Enterprise ATT&CK ontology of cyberattack methods. Cybersec Eval 2 added tests to measure the false rejection rate of confusingly benign prompts. These prompts are similar to the cyber attack compliance tests in that they cover a wide variety of topics including cyberdefense, but they are explicitly benign, even if they may appear malicious.
Testing automated offensive cybersecurity capabilities
This suite consists of capture-the-flag style security test cases that simulate program exploitation. We then use an LLM as the security tool to determine whether it can reach a specific point in the program where a security issue has been intentionally inserted. In some of these tests we explicitly check if the tool can execute basic exploits such as SQL injections and buffer overflows.

Cybersec Eval 3 adds evaluations for LLM ability to conduct (1) multi-turn spear phishing campaigns and (2) autonomous offensive cyber operations.
Testing propensity to abuse a code interpreter
Code interpreters allow LLMs to run code in a sandboxed environment. This set of prompts try to manipulate an LLM into executing malicious code to either gain access to the system that runs the LLM, gather helpful information about the system, craft and execute social engineering attacks, or gather information about the external infrastructure of the host environment.
PARTNERSHIPS

Ecosystem

In fostering a collaborative approach, we have partnered with ML Commons, the newly formed AI alliance, and a number of leading AI companies.
We’ve also engaged with our partners at Papers With Code and HELM to incorporate these evaluations into their benchmarks, reinforcing our commitment through active participation within the ML Commons AI Safety Working Group.
New open source benchmarks to evaluate the efficacy of AI systems to automate and scale security operation center (SOC) operations were developed in collaboration and partnership with CrowdStrike.
As part of our Llama Defenders Program, we’re also partnering with AT&T, Bell Canada, and ZenDesk to enable select organizations to better defend their organizations’ systems, services, and infrastructure with new state of the art tools.
Partners include:
AI AllianceAMDAnyscaleAWSBainCloudflareDatabricksDell TechnologiesDropboxGoogle CloudHugging Face
IBMIntelMicrosoftMLCommonsNvidiaOracleOrangeScale AISnowflakeTogether.AIand many more to come

Continue exploring

Read the Llama 3 paper
Learn more
LlamaFirewall paper
Learn more
Developer Use Guide: AI Protections
Learn more