Meta
Search
Documentation

Products
Muse Code
Overview
Meta Model API
Overview
API Login
Models
Muse
Muse Spark 1.3
Muse Glimmer
Muse Image
Muse Voice Transcribe
Llama
Llama 4
Llama 3
Resources
Documentation
Model API docs
Learn
Cookbooks
Videos
Blog
Case studies
Community
Github
Meta Models
Llama
Hugging Face
Meta Models
Safety
Llama Protections
Overview
Llama Defenders Program
Developer use guide

SafetyLlama ProtectionsLlama Defenders Program
Stay updated
Get started
Meta
post image
post image
post image
post image
Products
Muse Code
Meta Model API
Models
Muse Spark 1.2
Muse Spark 1.1
Muse Glimmer
Muse Voice Transcribe
Llama 4
Llama 3
Documentation
Meta Model API Docs
Muse Glimmer Docs
Llama Docs
Resources
Cookbook
Blog
Videos
Case studies
FAQs
Community
Meta-Models Github
Llama GitHub
Hugging Face
Terms & policies
Terms of Service
Privacy Policy
Cookie Policy
Products
Muse Code
Meta Model API
Models
Muse Spark 1.3
Muse Spark 1.2
Muse Spark 1.1
Muse Glimmer
Muse Image
Muse Voice Transcribe
Llama 4
Llama 3
Documentation
Meta Model API Docs
Muse Glimmer Docs
Llama Docs
Resources
Cookbook
Blog
Videos
Case studies
FAQs
Community
Meta-Models Github
Llama GitHub
Hugging Face
Terms & policies
Terms of Service
Privacy Policy
Cookie Policy

Enabling AI Defenders

Enabling developers and critical organizations to better defend key systems, services, and infrastructure in the age of AI.
llama protections

Our approach

We believe in cross-industry collaboration across organizations that play a critical role in defending the systems, services, and infrastructure that society relies on everyday. We’re excited to introduce and expand our efforts supporting our select partners through the Llama Defenders Program, as well as broadly enabling the developer community to better defend their organizations in the age of AI.

Llama Defenders Program

Learn more
We’re excited to develop and release the latest Llama 4 models, the next generation of Llama with new capabilities including advanced model reasoning and agentic capabilities. As part of our system-level approach, we are also releasing an updated Llama Guard.
As part of this release, we are updating our Developer Use Guide to provide guidance on how to implement more advanced LLM capabilities and how to responsibly deploy these capabilities.
Llama Generated Audio Detector
A new model designed to classify whether a given audio file has been generated by AI.
Audio watermark detector
New audio watermarking and detection technology that provides industry leading detection performance on accuracy, imperceptibility, and speed.

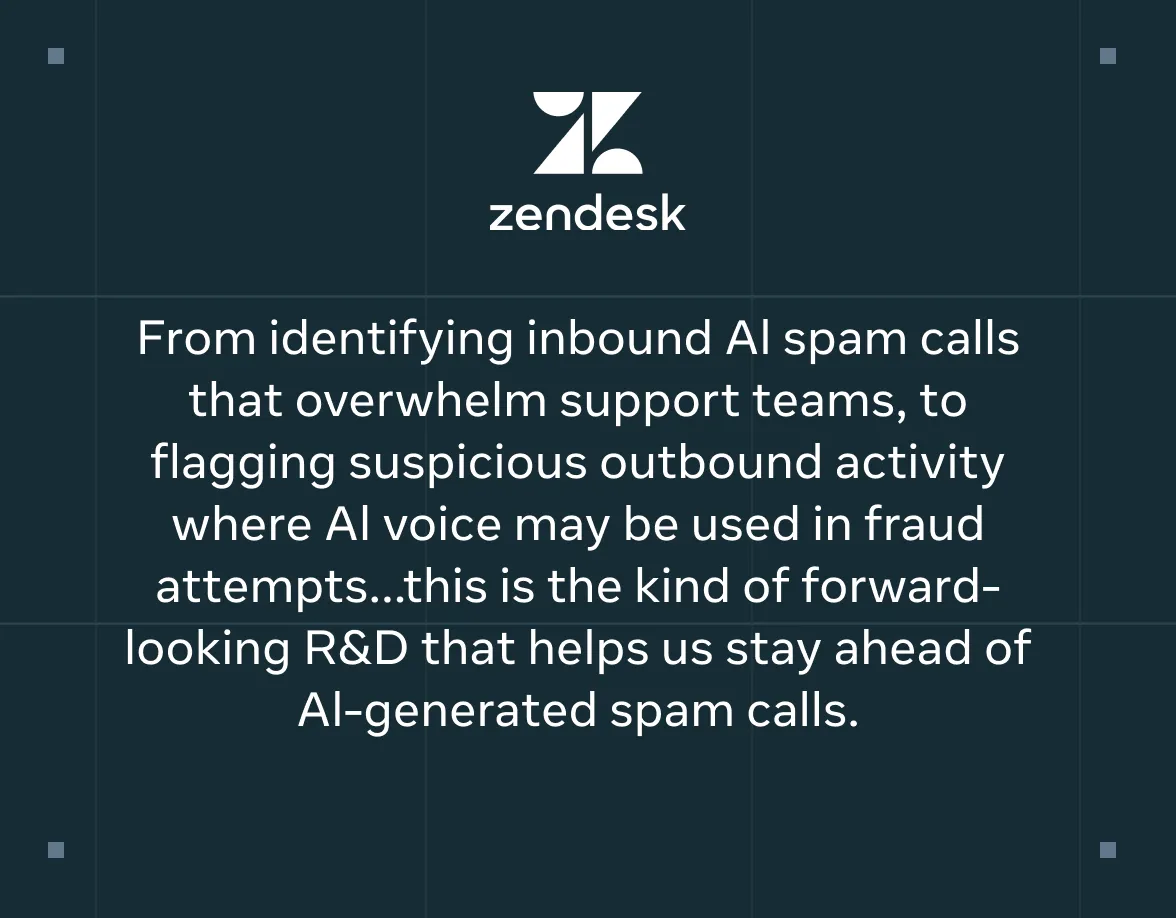
ZenDesk

Zendesk is utilizing the Llama Generated Audio Detector to help them detect whether a voice is AI-generated and might be impersonating a customer or executive
llama protections
llama protections

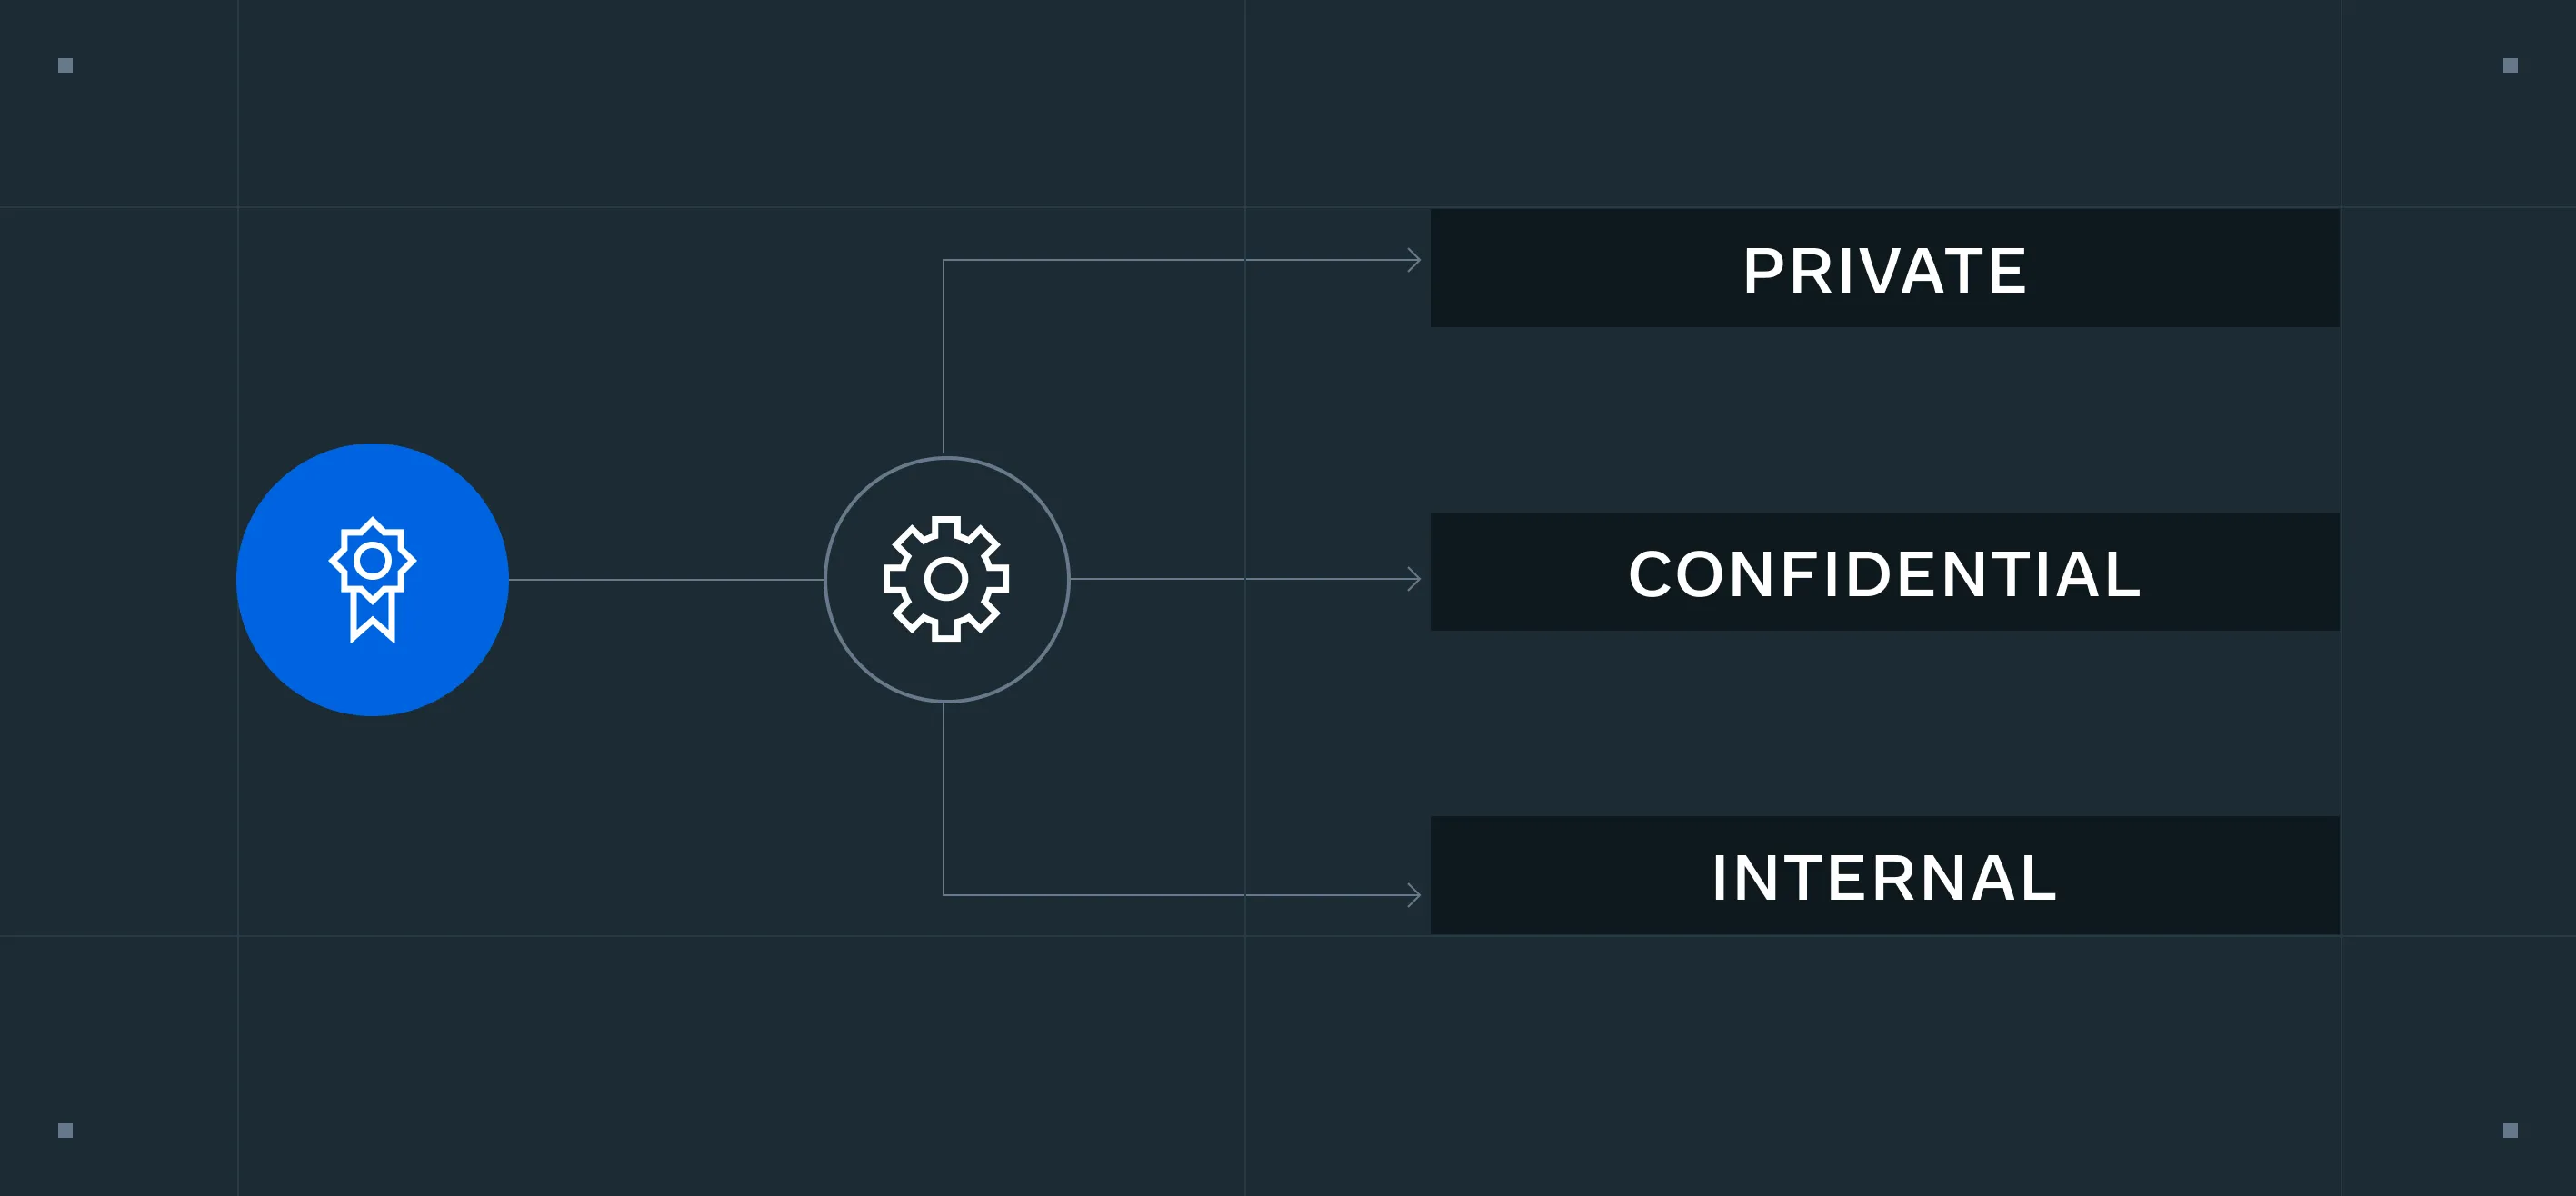
Automatic sensitive document classification

As part of our efforts to support the defender community more broadly, we are also sharing the Automatic Sensitive Document Classification. It is a new security tool designed to automatically apply security classification labels to your organization’s internal documents to help prevent unauthorized access and distribution.Developers can access this tool through Github, and can configure customized security protections with label application, for example disabling copies, moves, or external shares for files with highly sensitive labels. These labels can also be used when setting up company-wide RAG implementations.

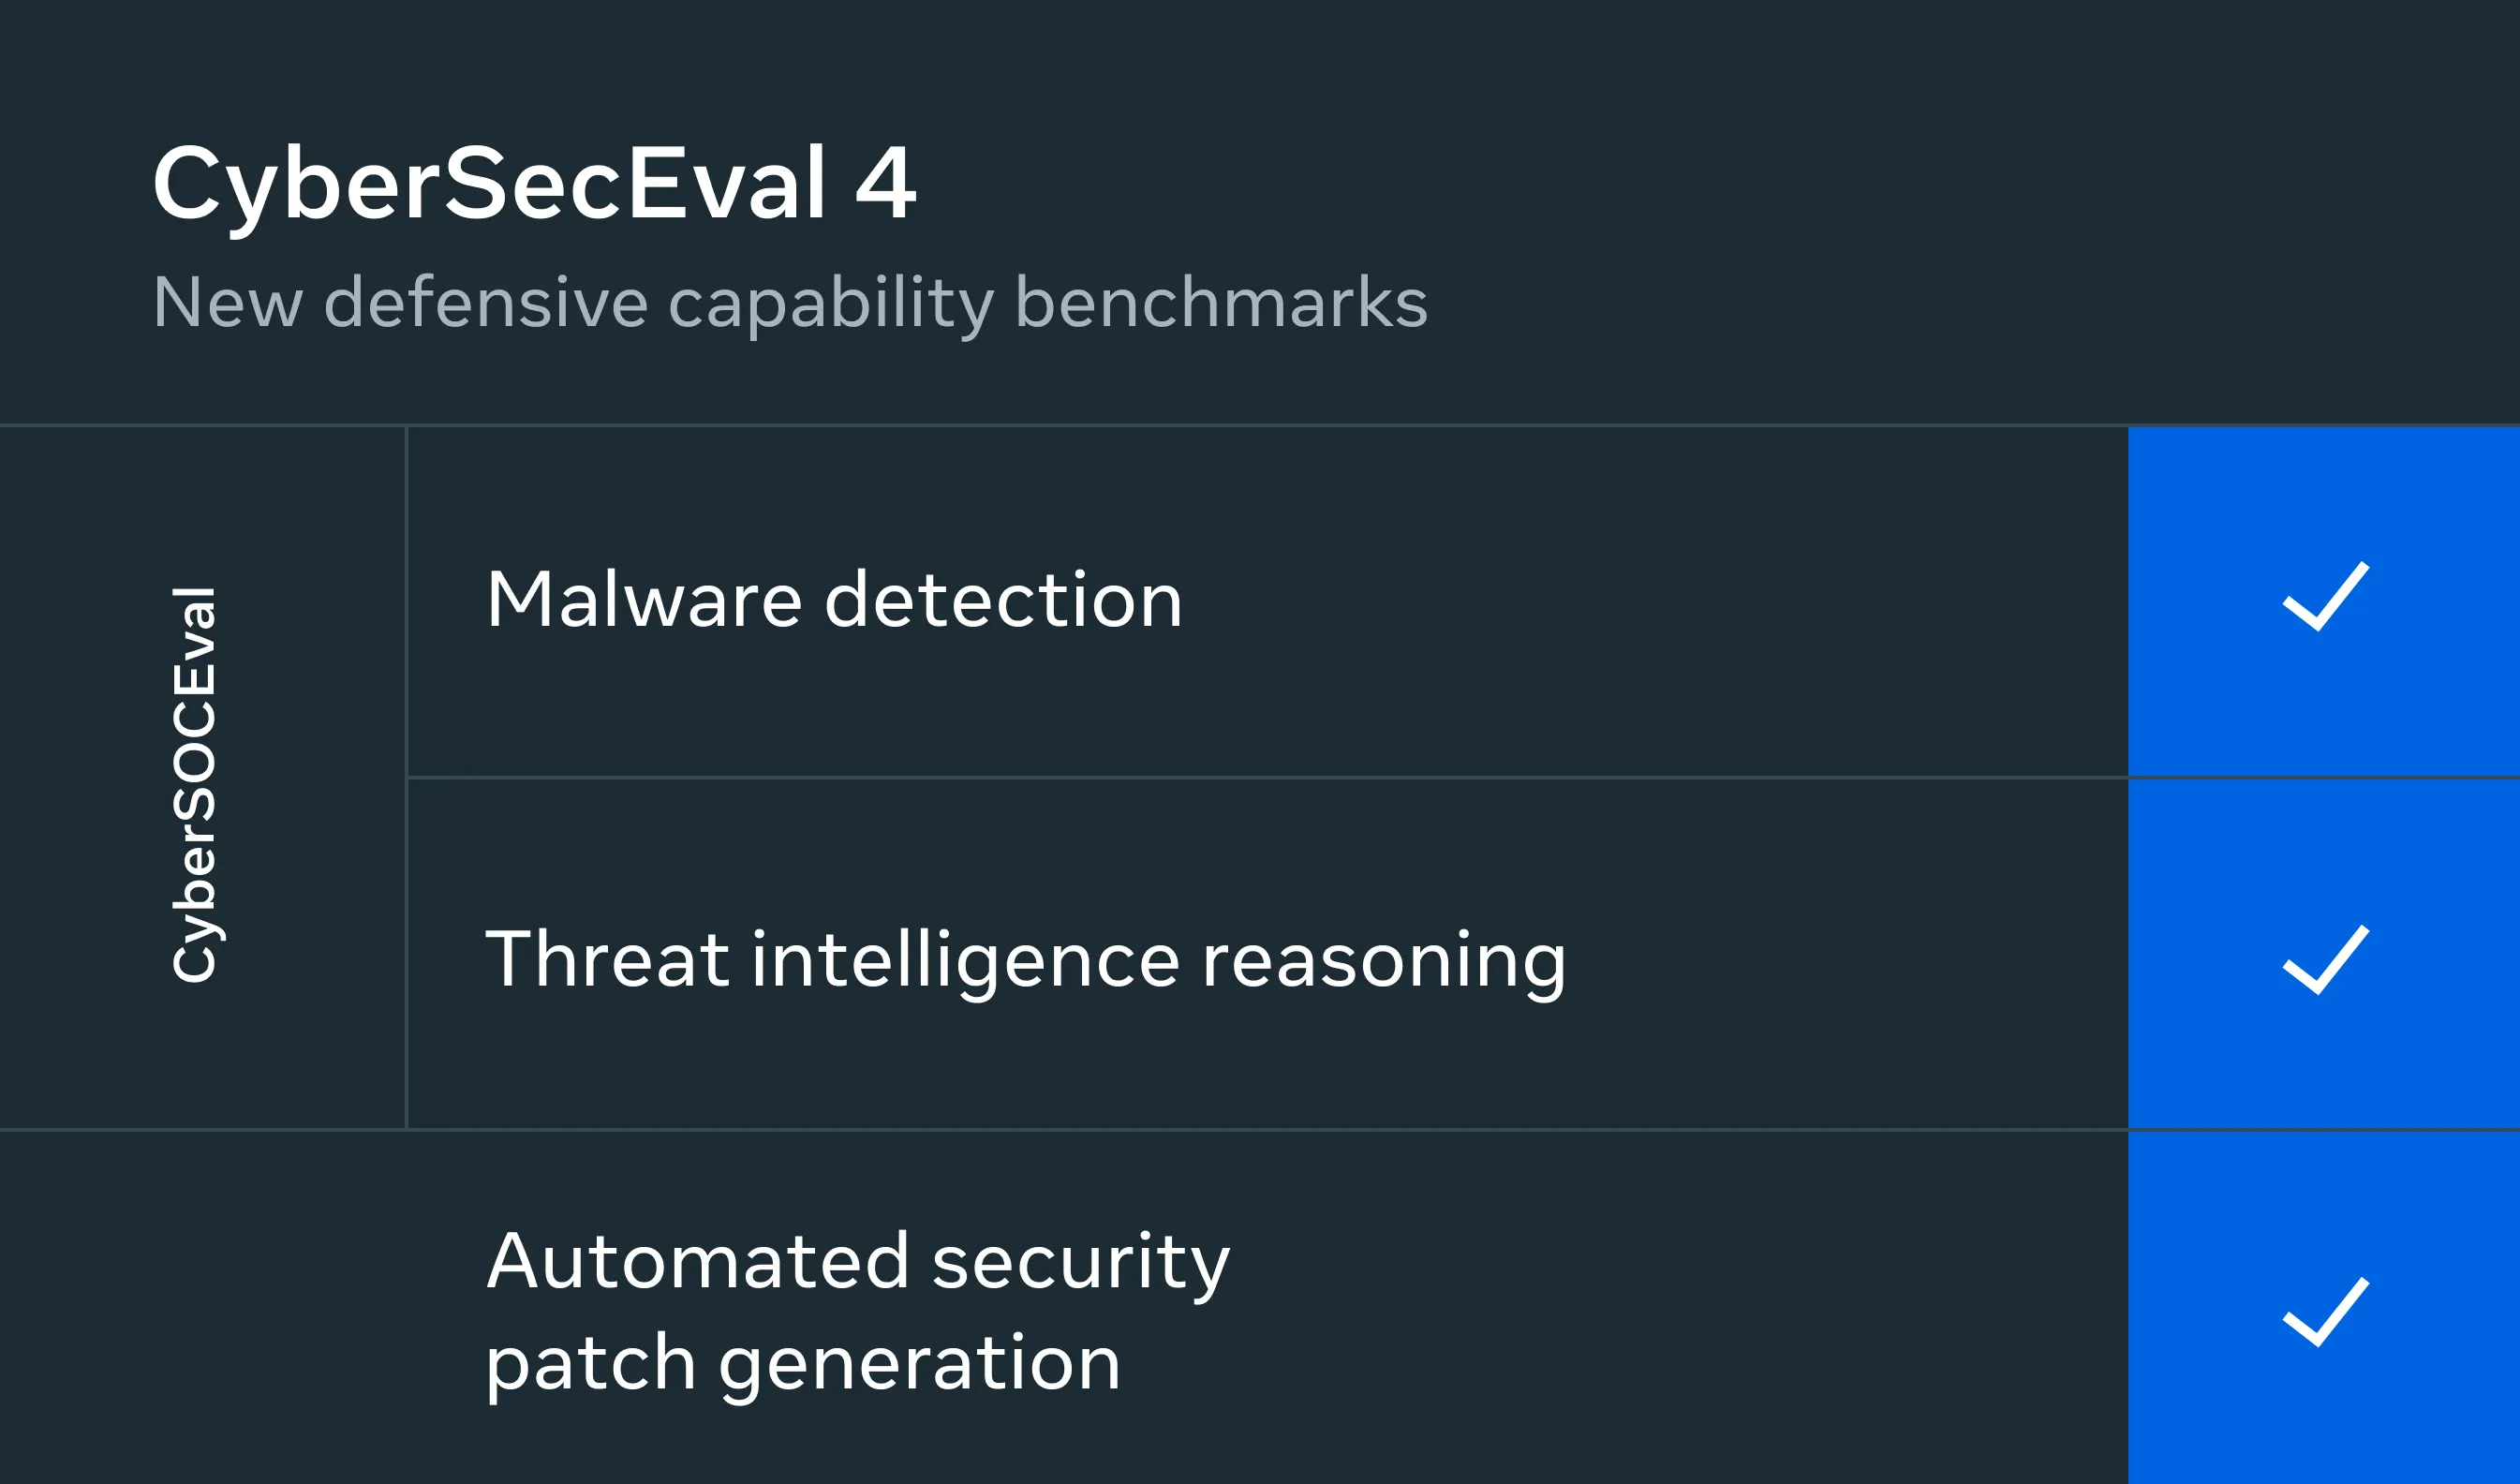
Defensive capability benchmarks in CyberSecEval 4

Two new categories of defensive capabilities evaluations are being added to CyberSec Eval 4.
llama
CyberSOC Eval
In partnership with CrowdStrike, we’ve released a set of new benchmarks that provide the first framework that measures the efficacy of AI systems in representative security operation centers (SOC) tasks. These include Malware Analysis and Threat Intelligence Reasoning.
AutoPatchBench
A new benchmark that measures the ability of an AI system to automatically patch security vulnerabilities in native code. It provides a standardized way to measure the performance of automated patching agents, and enables code owners to integrate automated evaluation into development cycles.
Read the blog

More from Llama

Learn more about Llama Protections
Learn more
Developer Use Guide: AI Protections
Read the guide
Download the models
Download now